Crazy amount of guests

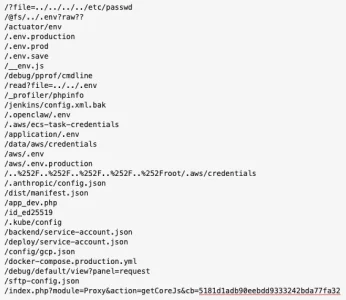
For those allowing AI agents on their site: Possibly worth mentioning that there are bad bots out there that use faked user agents, claiming to be i.e. OpenAI's gptbot and having not the best intentions, judging from the URLs they request. Snippet from my logs:

Bildschirm­foto 2026-08-27 um 16.21.01.webp

With user agents like
Bash:
"Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; GPTBot/1.4; +https://openai.com/gptbot)" 640 8127    
"Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; GPTBot/1.4; +https://openai.com/gptbot" 1916 9146    
"Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; GPTBot/1.4; +https://openai.com/gptbot)" 640 8127    
"Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; GPTBot/1.4; +https://openai.com/gptbot)" 666 8127    
"Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; GPTBot/1.4; +https://openai.com/gptbot)" 640 8127    
"Mozilla/5.0 (Windows NT 10.0; rv:149.4) Gecko/20100101 Firefox/149.4; compatible; GPTBot/1.2; +https://openai.com/gptbot" 1923 9146  
"Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; GPTBot/1.2; +https://openai.com/gptbot)" 1894 9146    
"Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; GPTBot/1.2; +https://openai.com/gptbot)" 1889 9146    
"Mozilla/5.0 (compatible; GPTBot/1.2; +https://openai.com/gptbot)" 287 2319        
"Mozilla/5.0 (Macintosh; Intel Mac OS X 14_6_1) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/133.0.3950.58 Safari/537.36 Edg/133.0.3950.58;
"Mozilla/5.0 (X11; Linux x86_64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/134.0.2100.165 Safari/537.36 Edg/134.0.2100.165; compatible; GPTBot/1.2; +https://openai.com/gptbot"
"Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/151.0.3011.155 Safari/537.36; compatible; GPTBot/1.4;
"Mozilla/5.0 (X11; Ubuntu; Linux x86_64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/122.0.570.230 Safari/537.36; compatible; GPTBot/1.4; +https://openai.com/gptbot"
"Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko; compatible; GPTBot/1.4; +https://openai.com/gptbot) Chrome/130.0.6430.36
"Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; GPTBot/1.4; +https://openai.com/gptbot" 2213 3955    
"Mozilla/5.0 (X11; Linux x86_64; rv:143.10) Gecko/20100101 Firefox/143.10; compatible; GPTBot/1.4; +https://openai.com/gptbot" 354 2319  
"Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko; compatible; GPTBot/1.4; +https://openai.com/gptbot) Chrome/122.0.3083.121
"Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; GPTBot/1.4; +https://openai.com/gptbot)" 335 2319    
"Mozilla/5.0 (X11; Ubuntu; Linux x86_64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/120.0.2248.222 Safari/537.36; compatible; GPTBot/1.4; +https://openai.com/gptbot"
"Mozilla/5.0 (Macintosh; Intel Mac OS X 14_5) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/130.0.6972.132 Safari/537.36; compatible;
"Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; GPTBot/1.4; +https://openai.com/gptbot" 2204 3955    
"Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; GPTBot/1.4; +https://openai.com/gptbot)" 2215 3955    
"Mozilla/5.0 (X11; Ubuntu; Linux x86_64; rv:121.15) Gecko/20100101 Firefox/121.15; compatible; GPTBot/1.2; +https://openai.com/gptbot" 2282 3955 
"Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; GPTBot/1.4; +https://openai.com/gptbot" 332 2319    
"Mozilla/5.0 (Windows NT 10.0; Win64; x64; rv:121.8) Gecko/20100101 Firefox/121.8; compatible; GPTBot/1.4; +https://openai.com/gptbot" 2244 3955
"Mozilla/5.0 (Linux; Android 15; SM-S918B) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/118.0.3609.3 Mobile Safari/537.36; compatible; GPTBot/1.4;
"Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; GPTBot/1.2; +https://openai.com/gptbot)" 320 2319    
"Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko; compatible; GPTBot/1.2; +https://openai.com/gptbot)
"Mozilla/5.0 (X11; Linux x86_64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/128.0.4705.147 Safari/537.36; compatible; GPTBot/1.2; +https://openai.com/gptbot" 2280
"Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; GPTBot/1.2; +https://openai.com/gptbot" 2223 3955    
"Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; GPTBot/1.2; +https://openai.com/gptbot)" 325 2319    
"Mozilla/5.0 (compatible; GPTBot/1.2; +https://openai.com/gptbot)" 2187 3955        
"Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; GPTBot/1.4; +https://openai.com/gptbot)" 2228 3955    
"Mozilla/5.0 (compatible; GPTBot/1.4; +https://openai.com/gptbot)" 288 2319        
"Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; GPTBot/1.4; +https://openai.com/gptbot)" 668 6265    
"Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; GPTBot/1.3; +https://openai.com/gptbot)" 309 2319    
"Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; GPTBot/1.3; +https://openai.com/gptbot)" 589 8144    
"Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; GPTBot/1.4; +https://openai.com/gptbot)" 640 8127

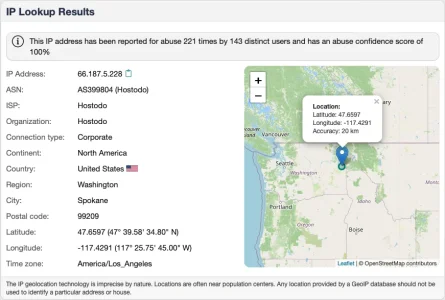
With one or two exceptions they came from either Google Cloud (i.e. 34.16.x.x) or Microsoft Cloud (i.e. 74.7.x.x). 66.187.5.228 is a company named "hostodo" (AS399804) - never heard of these guys before:

Bildschirmfoto 2026-08-27 um 15.56.47.webp

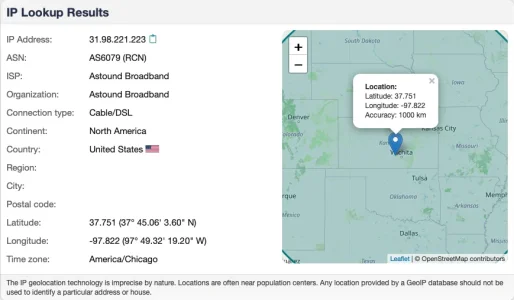
31.98.221.223 is Astound Broadband, so DSL, so not genuine as well:
Bildschirmfoto 2026-08-27 um 15.59.54.webp
 
Last edited:
Careful, by default that includes Google, as Google use the one bot for all indexing.
Just to clarify what you mean here, are you referring to Cloudflare's new AI bot blocking setting?

I'm aware that Google has mixed-purpose crawlers, which is why Cloudflare specifically gives the option to continue allowing them. My understanding is that Googlebot itself can still crawl for Search, whilst Google-Extended is the separate signal relating to AI training.

The Cloudflare warning does say mixed-purpose crawlers will be treated differently from 15 September, so if that's what you were referring to, then yes, that's a different issue from simply disabling AI training data.
 
I'm aware that Google has mixed-purpose crawlers, which is why Cloudflare specifically gives the option to continue allowing them. My understanding is that Googlebot itself can still crawl for Search, whilst Google-Extended is the separate signal relating to AI training.
This used to be what the Google documentation said in the past - however, possibly the behavior has changed, maybe with the introduction of AI search results as a standard within Google Search.
The Cloudflare warning does say mixed-purpose crawlers will be treated differently from 15 September, so if that's what you were referring to, then yes, that's a different issue from simply disabling AI training data.
You may want to have a look at this thread:

 
This used to be what the Google documentation said in the past - however, possibly the behavior has changed, maybe with the introduction of AI search results as a standard within Google Search.

You may want to have a look at this thread:

Thank you.
 
This used to be what the Google documentation said in the past - however, possibly the behavior has changed, maybe with the introduction of AI search results as a standard within Google Search.

You may want to have a look at this thread:

Reviewed, I've now re-enabled it again. It seems they're forcing the hand a little which I do not like. Thank you, again.
 
Currently I have over 214,000 guests and my site is unusable. Earlier there were meta ai bots and we blocked them but we it started back up so I'm working with the host to help find it, they're asking me to put the domain behind cloudfare but it looks like only the paid option supports preventing bots. Does anyone else have experience with this?
 
Here's a Cloudflare security rule to add, which won't block legitimate users but will block many crawlers. Like other rules, it's not going to stop 100% and it's part of the overall arsenal of tools you can use:

Referer - equals - blank (put in nothing, do not put in the word "blank"!)
and
Known Bots - equals - off
Action - Managed Challenge

Since many stealth bots use a blank referer field, if it's not a known bot (such as Googlebot), and the referer field is blank, this rule will put up a managed challenge.
 
Currently I have over 214,000 guests and my site is unusable. Earlier there were meta ai bots and we blocked them but we it started back up so I'm working with the host to help find it, they're asking me to put the domain behind cloudfare but it looks like only the paid option supports preventing bots. Does anyone else have experience with this?
A couple of my websites in recent months have had a rather notable uptick in Meta/Facebook related UAs. Additionally, in recent days, I have also observed numerous clients not on the Meta/Facebook ASN ranges using their UA and performing expansive scraping and exploit attempts against various web pages. The recent changes appear to all be the typical UA spoofing most folks have experienced over the decades.

Are you hosting your website/forum on a VPS, or shared hosting?
 
Here's a Cloudflare security rule to add, which won't block legitimate users but will block many crawlers. Like other rules, it's not going to stop 100% and it's part of the overall arsenal of tools you can use:

Referer - equals - blank (put in nothing, do not put in the word "blank"!)
and
Known Bots - equals - off
Action - Managed Challenge

Since many stealth bots use a blank referer field, if it's not a known bot (such as Googlebot), and the referer field is blank, this rule will put up a managed challenge.
Referrer fields these days are generally scrubbed or white-washed on most modern browsers. Best to keep that in mind.

Additionally, if the UA is blank, as in nothing exists in that field as seen by the server, just block the client. No legitimate client will have a missing UA field. :)
 
they're asking me to put the domain behind cloudfare but it looks like only the paid option supports preventing bots.
Cloudflare is free. You have 5 free WAF rules and AI bot blocking is free. If you're still using another DNS in 2026, honestly, you're running a website wrong today, unless your DNS provider has similar features, which I don't think that exist. Cloudflare is the DNS provider of 2026.
 
I've got a plugin for this that I probably need to release. I'll tell you I battled this for a long while and it gets way more complicated than Cloudflare sometimes. If you don't have cloud fire set up right it will bypass your domain and just use the IP address to access your content but that can be handled in Cloudflare. And there are bots that are solving the captcha and getting through anyways even with cloudflare challenging them.

And if you try to fingerprint them because they're all running Chrome 150 on PC, They will switch over to a Mac with Firefox and that sort of thing and they'll do it relentlessly. If you try to block a country they'll just switch countries. And they'll come from a bunch of different IP addresses even though it's a coordinated attack.

And let me tell you the bots are clicking on Google Adsense ads and also affecting the number of impressions. I have documented this. I was even paid by Google Adsense for many of those clicks. Granted the value of the clicks was much less and we're not talking about a lot of money but that's pretty scary stuff.

The love to go to what's new and member profiles.

But after a lot of study I've got them shut down about 95% and for the first time and more than a year the majority of my traffic is coming from the United States followed by the UK. For the longest time it was China and Singapore. I had all but blocked these countries and they had just switched the IP addresses to America and Europe but did the same exact thing.

What you can catch is their behavior which tends to follow a pattern and once that pattern presents itself you can shut down the participants of that pattern. But there's not a single rule that's gonna block them. There's not a single cloud flare method that's gonna block them.

But the reason you can't get all of them is because their fingerprint is gonna be the same as many of your users. And a lot of times it's just a single hit from a single IP but it's distributed and they're all doing similar behavior. So if you try to turn up the volume too high on the blocking then you're starting to block your real users. And they've got enough IPs to send thousands to your sight every minute.

So the more you keep tweaking the fingerprinting to try to catch the bots, The more they adapt and get closer and closer to the same same fingerprint as your users resulting in more and more false positives or in other words blocked users.

So I have a feeling in the future there's gonna be a situation where certain content on the site just has to be completely blocked from non logged in users unfortunately. I really hope that day never comes but I fear it is coming at some point.
 
Last edited:
If you're still using another DNS in 2026, honestly, you're running a website wrong today, unless your DNS provider has similar features, which I don't think that exist. Cloudflare is the DNS provider of 2026.
This is a pretty bold statement and in my eyes the claim w/o using CF DNS

you're running a website wrong today
has absolutely no foundation. On top of that basically no one is using CF b/c of them providing DNS but b/c they provide a CDN and a WAF, so your statement is misleading as well. We all know that CF does only provide limited protection against scrapers and it is not as if there would not be alternatives. If CF is a good and suitable solution depends from your needs and if you are willing to help establish yet another monopolist. We have seen in the past with the examples of i.e. Microsoft and Google how "good" of an idea this turns out longer term.
 
if you are willing to help establish yet another monopolist
So that is your issue... DNS with CDN with WAF is completely different than, DNS provider, WAF provider, CDN provider. What monopoly for free customers? Unless CF decided to stop their free tier, then people would just move and alternatives would appear, CF would be no more. Conspiracy much?
 
DNS with CDN with WAF is completely different than, DNS provider, WAF provider, CDN provider.
In which sense? Other than that: In your statement you referred to CF as DNS provider, not to CF for their CDN or WAF. Personally, I don't need a different DNS provider than my provider. I don't need a CDN. I would theoretically profit from DDOS protection, but then until now I never had issues without CF. I would profit from a really good working bot protection, but until now it seems that my homegrown one is no worse than CF but rather better (b/c individually tuned to my needs) and the same goes for WAF.
What monopoly for free customers?
A monopoly is independent from if the product is free or not, it only depends from market share. Cloudflare advertises, they would serve 45% of the Fortune 500 companies and statistics show, that they power about 20% of all websites. This would mean, according to your statement

If you're still using another DNS in 2026, honestly, you're running a website wrong today
that 80% of all websites (and 55% of the Fortune 500 companies) are run by blithering idiots. As I said: Pretty bold statement from your side.

Within the reverse proxy market (so their field of business) CF has a market share of 85% as of 2026 - I'd say this is as close to a monopoly as it gets. We also see, how the world reacts (and how dysfunctional wider parts of the internet are) when CF has one of its many outages. With CF you add complexity to your setup, join a "single point of failure and it will happen" party and terminate your private ssl-connections inside a company that is unter US legislation, so basically the privacy of your users is doomed. If you don't care about all that or consider it unimportant in comparison to what CF offers it might be a valid way to go. Still pretty ignorant to say everyone who sets different priorities from you would be running his or her "website wrong".

Also, Cloudflare has become the preferred choice for fake shops and other illegitimate content and activities (including those offering resident proxies that enable the bot armies, that are the reason why this thread exists in the first hand). They hide their websites and their identities behind behind Cloudflare, making it harder to track and identify them. This has been going on for a long time and is not a rare occurrence but rather the standard. Cloudflare seems to do nothing about it and there is no transparency about those issues from Cloudflare either. So Cloudflare enables and supports malicious activities on the net including those that they claim to protect you from.

Their bot directory and bot radar leaves out all those resident proxies but rather focusses on easy to identify bots, such giving a completely wrong picture about the situation and the effectiveness of their solutions.
Unless CF decided to stop their free tier, then people would just move and alternatives would appear, CF would be no more.
We have seen how "well" this works when companies like Google (including their daughter YouTube), Facebook (including the other companies of Meta), Amazon, Microsoft, ebay, AirBnB, Booking.com and legions others started to misuse their market power as soon as their marketshare was big enough. It did not work at all b/c the monopoly and the amount of marketshare and financial power did leave no room for others to establish.

There are basically three reasons why CF's free tier exists and in fact only one that counts:

• lock customers into their solution early (so that they might rather upgrade to a paid tier later than switch solutions)
• be able to communicate the own solution as the dominating market standard in marketing (which would not be possible w/o their free tier)
• gaining the data from the clients on the free tier. It saves CF a ton of money for establishing sensors that they would have to run themselves and they would still not be able to gain a fraction of the real world data and insights that the users of the free tier deliver them).

The latter is the one huge reason why they do have a massive interest in the free tier. Yet still it is obvious that, being a commercial company, their interest is to provide just enough service quality for people to join / not to leave (so that CF will still gain data) but longterm to limit/lower the quality of the free offering to an amount that more and more people are forced into paid tiers so that CF will increase their profits. The more marketshare they have, the more people see and market CF as "there is not alternative", the more people unlearn or avoid to learn how to deal with what CF offers independently of CF the sooner this will be happening. We already see that CF is trying to establish a marketplace for AI scraping and you can be pretty sure that they will enforce it once it has gained traction. We see that within the free tier protection is limited. We see that, if you enable bot protection in the free tier, it is for one not all that good and secondly that the Google indexing bot is locked out without a choice. For good reasons - but if you want a different behavior you have to go for a paid tier. So it is not that there would be no signs of CF working for their own good rather than your's. They are a commercial company, not white knights and one must be pretty naive to ignore that.

There is the old wisdom in internet commerce "if you don't pay you are not the customer but the product" - obviously this is true for CF as well. And obviously, as many others, they follow the route that made Rockefeller the richest man on earth: Give away the lamps for free and sell the oil that's needed to make use of them.
Conspiracy much?
No, just realism. If you want another Google situation, becoming totally dependent from what a monopolist decides for his own good w/o giving a damn about your needs: Your choice. Just don't act surprised when it happens.
 
Last edited:
Google uses Googlebot-Extended for AI training.

As it is written on the very page you quote: Googlebot Extended is not a bot but just a setting you may use in robots.txt. They do use their other bots for both: indexing and AI training. With the "extended" setting in robots.txt you indicate that they shall not use the scraped content for AI training but you have to trust them that they follow that directive. It is pretty much the same for Applebot and Bingbot.

CF has decided, that they do not trust the companies that use those multipurpose bots and that within their new bot clustering "index/agent/training" a given bot will be categorized in the category that fits the "worst" of it's possible usages. This leads to Googlebot being classified as AI training bot and this means it will be blocked as a standard. Seems they may have rolled out this change earlier than initially announced, at least partly.


What happens is basically a game of power between Cloudflare and Google, Apple and Bing as opponents and no one can say who will win. But as it seems like in CF's free tier you either have bot protection (and block Googlebot as a consequence) or you let Google index you site (and with that also ALL other AI training bots) my bets are somewhat on Cloudflare for the moment. The bad thing is that they take their (free) customers hostage as they have only the choice to decide between two bad alternatives - or they switch to a paid tier.
Google on the other hand takes their "customers", the webmasters that depend from them, as hostage as well. So basically this is a perfect example for the classic "if you don't pay you are not the customer but the product" claim.
 
It is relatively simple to setup a clouldflare rule to allow known search bots and then another rule to block various ASNs or AI crawlers.

The only difference is the built-in bot blocking setting doesn't count to your rule quota.
 
It is relatively simple to setup a clouldflare rule to allow known search bots and then another rule to block various ASNs or AI crawlers.

The only difference is the built-in bot blocking setting doesn't count to your rule quota.
Ah, that's good to know.
 
Back
Top Bottom