Crazy amount of guests

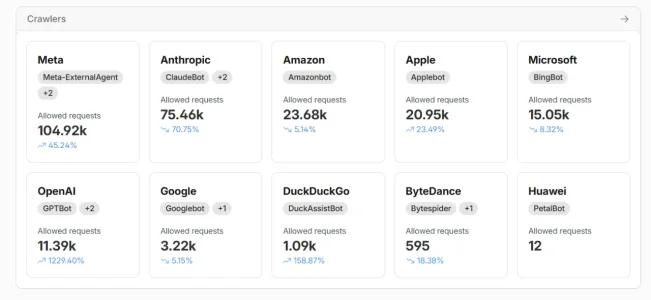
Anyone else seeing a notable uptick in the past 48 hours of Facebook's bot bearing the UA of Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/145.0.0.0 Safari/537.36 (compatible; meta-externalagent/1.1 (+https://developers.facebook.com/docs/sharing/webmasters/crawler)) rapidly hitting random pages? From my logs, all of 57.141.4.0/24 in this instance is being utilized to evade rate limiting.

Normally I'm not too concerned, but this is absolutely ignoring robots.txt (not like anyone respects it any more except legacy search engines) and is happening in bursts, very similar to our Asian-scraper botnet friends.
View attachment 342336

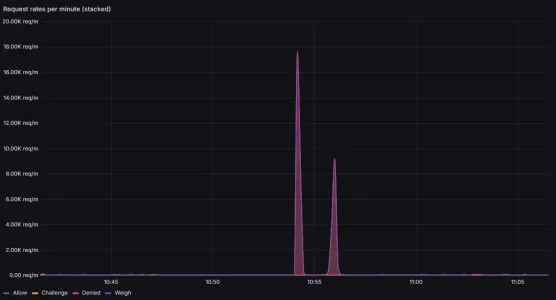
Image above is from one of my Anubis instances blocking whatever is going on with this bot from Meta/Facebook.


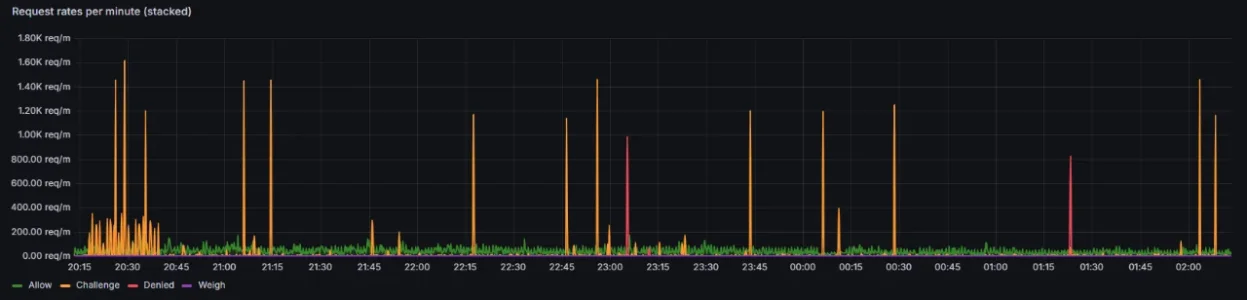
Edit; As an update, the Facebook/Meta bots came to a close, then a rather large flood of challenges dished out shortly thereafter.

View attachment 342337

Lots of reports for that /24 -- which isn't all that large in the grand scheme of things. Definitely legit Meta IP space though: https://www.abuseipdb.com/check-block/57.141.4.0/24

Block it!
 
I had Meta hit my site last week or so, nearly a million in 24hrs from it. It got aggressive. This is just todays... but its still aggressive.

Screenshot 2026-08-07 142609.webp
 
Last edited:
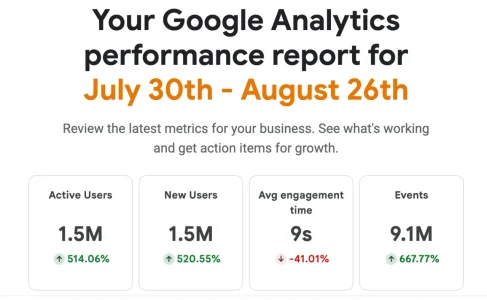
If the bots are largely from one concentrated area like China or Singapore, validate that the same traffic in Google Analytics is even hitting your ORIGIN or CDN. The reason that I'm saying this specifically is because it looks like there can be a flood of traffic and it can be pinging Google with your Measurement-ID. The Measurement-ID is apparently public in general, and something unusual is happening that's been documented frequently about it. Apparently it can even be just ghost bots not even hitting your website or CDN:

 
Meta is trying to play catchup with all the other AI entities out there
The action closely follows Zuck's doubling down on going full AI mode, despite massive financial losses because of it and the mood among Meta's employees hitting rock bottom. It was in the news this week or so. And today was another article where Meta's original fine of 300ish million US$ was pushed up to nearly a billion by a US judge, for failing to implement effective protection measures for kids on the platform. They'll appeal of course, but they're absolutely desperate to score some wins and secure more funding for their AI dreams, and they won't let a measly robots.txt stand in the way. Shields up!

As for bots hitting various resource-intensive URLs like /search or /whats-new , kind reminder of another post earlier in this thread (was it @zeeb0t 's perhaps?) with a filter for URLs that should be carefully controlled for visitors that are not authenticated or at least do not have a server session already (bots hitting directly those URLs). They would have no business trying to see the list of members, or settings for their own account (which doesn't exist), or private messages. This is my variant of it, feel free to adjust as needed.

Code:
(http.request.method eq "GET" and not http.cookie contains "xf_user=" and (
http.request.uri.path wildcard r"/forums/*" or
http.request.uri.path wildcard r"/threads/*" or
http.request.uri.path wildcard r"/whats-new/*" or
http.request.uri.path wildcard r"/search/*" or
http.request.uri.path wildcard r"/members/*" or
http.request.uri.path wildcard r"/account/*" or
http.request.uri.path wildcard r"/direct-messages/*" or
http.request.uri.path wildcard r"/misc/*"
))
 
http.request.uri.path wildcard r"/forums/" or http.request.uri.path wildcard r"/threads/" or
That takes out every bot from your forums and content as they all use GET to grab the content. The only load bearing ones are /search and /whats-new which create search queries on your DB. Everything else you can mitigate with caching.
 
That takes out every bot from your forums and content as they all use GET to grab the content. The only load bearing ones are /search and /whats-new which create search queries on your DB. Everything else you can mitigate with caching.
Once more it is the question of the goal: Do you want to block bots from scraping or do you (as you do) just care for the load of the server. Both are valid approaches but obviously different goals require different measures. Other than that we have seen earlier up the thread a case where a bot swarm requested a normal thread url at scale, thus causing massive load as well, so you statement may be correct for many situations but clearly not universally.
 
That takes out every bot from your forums and content as they all use GET to grab the content.
Correct, hence the suggestion that the rule may need adjustments for others' taste.

I have personally reached the conclusion that I have neither a commitment towards companies operating bots nor anything to benefit from them ingesting my site's contents for any reason, and they're getting challenged. Google has betrayed the agreement that they can ingest content and index it so that they drive traffic to (my) sites through search results; I do not see why I should continue allowing access when I no longer get anything in return, other than the hosting bill for excess server load.

But everyone's free to make up their own mind on this, and adjust those rules accordingly.
 
I'd like to ask for some help please - in my efforts to combat high spam from a bunch of countries that is massively affecting our ad revenue, I'm trying to make it so countries outside of a select few get a CF managed challenge, with the exception that logged in users do not get these challenges. I currently have this Managed Challenge rule:

(not ip.src.country in {"AT" "AU" "BE" "CA" "DK" "FI" "FR" "DE" "IE" "IT" "NZ" "NL" "NO" "ES" "CH" "GB" "US" "SE" "LU"})
and http.request.method eq "GET"
and not cf.client.bot

As well as this xf_user cookie Skip rule:
http.host in {
"site.com"
"www.site.com"
"data.site.com"
"www.data.site.com"
}
and any(http.request.cookies["xf_user"][*] ne "")

I've also added a cache bypass to the cache rules for logged in users. But my users outside of these select countries see broken images, no matter what I do. For example, avatars, which are hosted on data.website.com, are showing as broken. They're not getting any CF challenges so I know that part is working, but images refuse to load. Does anyone know what I may have done wrong?
 
Caching is one of the most unpredictable things. If it isn't working, undo it so your users aren't being negatively affected, then start again. Always make caching changes one at a time, drop all caches, test them over a day or two to see if any reports come back.

One rule is also easier for that:

(not ip.src.country in {"AT" "AU" "BE" "CA" "DK" "FI" "FR" "DE" "IE" "IT" "NZ" "NL" "NO" "ES" "CH" "GB" "US" "SE" "LU"})
and http.request.method eq "GET"
and not cf.client.bot
and not any(http.request.cookies["xf_user"][*] ne "")

Potential issue with caching could be that your challenge isn't scoped by host, so images, css, js, etc, are all within that, overriding your caching rule.

If you want to exclude static assets, then add a variation of either, depending on what you plan allows.

and not http.request.uri.path.extension in {"css" "js" "jpg" "jpeg" "png" "gif" "webp" "svg" "ico" "woff" "woff2" "ttf" "mp4" "webm"}

Or path matching.

and not starts_with(http.request.uri.path, "/data/")
and not starts_with(http.request.uri.path, "/js/")
and not starts_with(http.request.uri.path, "/styles/")

Head only.

and not any(http.request.headers["sec-fetch-dest"][*] in {"image" "style" "script" "font" "empty"})

Or completed, which I would test thoroughly to ensure it acts accordingly:

(not ip.src.country in {"AT" "AU" "BE" "CA" "DK" "FI" "FR" "DE" "IE" "IT" "NZ" "NL" "NO" "ES" "CH" "GB" "US" "SE" "LU"})
and http.request.method eq "GET"
and not cf.client.bot
and not any(http.request.cookies["xf_user"][*] ne "")
and http.host in {"yoursite.com" "www.yoursite.com"}
and not any(http.request.headers["sec-fetch-dest"][*] in {"image" "style" "script" "font" "empty"})
 
Last edited:
After doing some "fun work" reconfiguring Nginx and Anubis this past week... web attacks and harmful scrapers have been getting the door shut in their face while legitimate clients, indexer bots, among other clean users, are facing either no challenge level, e.g., valid user cookie check or whitelisted range and bypassing anubis, or having a lessened challenge level in general. Problematic clients, toxic ASN's, among other undesirable clients, are just being given a harsh challenge level - Level 6+ or flat out blocked. The honey pot has been delivering delicious tainted content as well - eat up glorious scrapers, and keep them hallucinations going. ;)

brave-08-17_02-13-d0894b02-5f50-4b8e-b69f-527e82fae7b0.webp
Had an event prior to this chart above that was pushing 14k requests a minute for about 3 to 4 minutes of just mass content grab attempts. All of it was slapped dead at Anubis. Couldn't imagine the physical resource strain that would have put on my stuff without the filtering in place.

Edit; Spelling errors...
 
Last edited:
AS214483 is a new player to the field, hitting /search aggressively.
https://www.peeringdb.com/net/37989 - seems to be a fairly new player in the internet world. Peering points being predominately in the West USA.

Website looks suspect as all can get though. Masquerading as a business-based ISP (B2B), but seems to indicate as "coming soon".
 
Website looks suspect as all can get though. Masquerading as a business-based ISP (B2B), but seems to indicate as "coming soon".
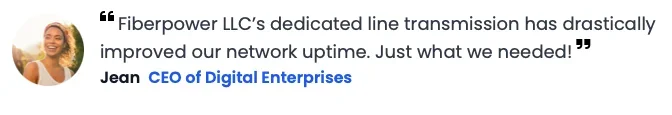
Depending where you look their website is either usfiberpower.com, which is full of fake testimonials like these (look at the "company names" ;)) and selling internet access:
Bildschirm­foto 2026-08-26 um 17.03.03.webp

Bildschirm­foto 2026-08-26 um 17.03.11.webp

Bildschirm­foto 2026-08-26 um 17.03.17.webp

Or the website is fiberstate.com which is a hosting company and markets itself as "Carrier Neutral Data Center" (which is probably a more posh wording for "black hat hoster").
 
hit 250k yesterday. lol - think it was a ddos attack but cloudflare didnt detect it and webserver had no issues as guests are served static content.
 
Guess I broke someones bot today...
brave-08-26_17-04-8b9ea8bc-7f80-4655-8c21-3faa7af1ebe4.webp

Me: i dunno... but oh well!
2c3yd6.webp

@MentaL they come in batches, sometimes it's enough to make things go sideways, other times it's just background noise. Glad to see properly configured caches and settings allowed you to stave off that issue.
 
Me: i dunno... but oh well!
If I had of been drinking coffee at this moment, it would be all over my screen. Love it.

Screenshot 2026-08-27 082454.webp

Mine was doing so well... until about 20hrs ago when this new ASN mentioned above started ramping up and trying to hit my search. My solve rate was much better, everything before this catching the nasty stuff... and this being last, I can't fathom any other purpose other than it being a malicious attack on sites search function.
 
Back
Top Bottom