
You are using an out of date browser. It may not display this or other websites correctly.
You should upgrade or use an alternative browser.
You should upgrade or use an alternative browser.
Crazy amount of guests
- Thread starter Levina
- Start date
-
- Tags
- bot swarms guests

Legit users tend to request that lil' relic of the past (favicon.ico). However, probing bots also will request that files existence and then begin further probing.I don't know what the deal is, but my top path is/favicon.ico. It's almost double the second top path in the list, which is/cdn-cgi/rum. And that doesn't even exist on our server.
Not a clue about that cdn-cgi access though. Looks like some sort of attack vector, or some sort of misconfigured web service? https://developers.cloudflare.com/fundamentals/reference/cdn-cgi-endpoint/
The part in red i believe has the issue, regex problem. The / needs to be escaped within the regex 'or' match segment.Could someone give an opinion on the .htaccess code below please (haven't added it yet). After my surge to 1400 in the guest list yesterday, I investigated. Whereas previously, the bots were 99.9% hitting whats new and none of them had a referer, they have upped their strategy and now have added a referer. Had this analysed by Claude which showed they were doing this by mirroring the path they requested to become the referer. And as no genuine guest would ever have a referer like that, there might be a way to block them via .htaccess. So I wondered if someone could take a look at this .htaccess code please. Which blocks any visitor that has the request page as a referer but exempts registered members. I'm not going to blindly add that to .htaccess so an opinion on the code would be appreciated. The code includes other paths as well because there are a small number of bots going to those paths as well and when analysed, they were also faking a mirrored path referer.
I know I could just remove the referer element from the rule and challenge all genuine guests but I'd like to think there was a way of beating the bots and avoiding challenging genuine guests. Also if this did work I could narrow down how many were actually solving the challenge or not. Additionally this would BLOCK them rather than challenging them.
<IfModule mod_rewrite.c>
RewriteEngine On
RewriteCond %{HTTP_COOKIE} !xf_user
RewriteCond %{REQUEST_URI} ^/(whats-new|search|members|posts|ams|misc/cookies)
RewriteCond %{HTTP_REFERER} ^https?://([^/]+)(/.*)?$
RewriteCond %{HTTP_HOST} ^%1$
RewriteCond %{REQUEST_URI} ^%2$
RewriteRule ^ - [F,L]
</IfModule>
Edit - claude thinks it's a self referencing script creating the referer. However I suppose even if this worked they could reprogram the bots to add some different kind of referer as any referer would allow them to pass - but that would take a lot of effort for whoever was behind the bot behaviour presumably?
Edit 2 - I wonder if the same botmaster can read this post on here!
Code:
<IfModule mod_rewrite.c>
RewriteEngine On
RewriteCond %{HTTP_COOKIE} !xf_user
RewriteCond %{REQUEST_URI} ^\/(whats-new|search|members|posts|ams|misc\/cookies)
RewriteCond %{HTTP_REFERER} ^https?://([^/]+)(/.*)?$
RewriteCond %{HTTP_HOST} ^%1$
RewriteCond %{REQUEST_URI} ^%2$
RewriteRule ^ - [F,L]
</IfModule>
https://regex101.com/r/cdZmI3/1/unit-tests
Not knocking on the solution that you've found... but myself personally, I would rather filter out this abusive scraper stuff at an edge server or intermediate server and never let it reach my actual websites.Completely eradicated the issue on my forum...no Cloudflare or cumbersome add-on needed. Go over to https://www.xf2addons.com/ Andy has the fix.
Oh, there's a throwback to the early 2000s when folks were getting all up in a bunch that random websites were suddenly blocking incorrect referrer/origins so that they could no longer hotlink images. A few, even as you said, began replacing the image with something very naughty or just throwing a massive "DONT HOTLINK IMAGES FROM OUR WEBSITE!!" as a replacement image. That was a hot-issue for quite some time until image hosts began to pop up then services like AWS's s3 became a thing.I've been blocking hotlinking for at least 25 years now, using htaccess. It's one of those things we discovered in our logs--other sites using our bandwidth to display our images on their sites, which is wrong for all sorts of reasons. (It's like using an IMG tag where the source of the image is hosted on someone else's site.) It's nice having that option in CF with the flick of a switch, so we don't have to mess around with htaccess as much.
Back in those days, some of the more "adventurous" admins used to serve those sites a photo in response. So, rather than display the actual image linked to, htaccess could rewrite that to send an image of the admin's choice. Sometimes they were warnings (along the lines of "image linked without permission" or "stolen image!"), but the more adventurous of those occasionally got a bit vile.
It very likely is. Larger forums (or forums with a lot of history) tend to get slammed very hard.I wonder if your 882k bots are the same bots as my 779k?I mean - is this the same botswarm hitting all of us - same botmaster somewhere? Surely there can't be others?
It's a classic game of whack-a-mole or cat-n-mouse - however you see calling it, it fits the definition. With the right configurations active, ****listing of problematic/toxic ASNs, and expansive 'hair-combing' through access logs, will you be able to get a decent handle on the issue.It's a bit mad the whole thing. I mean there are websites on the internet telling people how to bypass cloudflare using pupeteer and headless browsers.
It's an ever evolving issue, and it's a matter of time until those script kiddies begin to expand their horizons past Cloudflares bot-blocker stuff. At that point, I'm talking about those same groups finding means and ways to evade and get past Proof of Work tests (Anubis, SafeLine, etc.) and per-server custom created bot-checks (which primarily revolve around basic PoW and captcha variants/implementations). I hope that day doesn't come, but I feel it will in the coming year or two.

Done that. I sent the middle finger back. I found it funny at the time.Back in those days, some of the more "adventurous" admins used to serve those sites a photo in response.
using pupeteer and headless browsers.

Bot fight mode covers that already.
Thank you very much. Much appreciated. In the end I'm not going to use that regex in .htaccess, because I removed my referer from the rule to see if it reduced the numbers of bots faking a referer. And it made no difference at all. So referer or not, a percentage were still solving the challenges.Legit users tend to request that lil' relic of the past (favicon.ico). However, probing bots also will request that files existence and then begin further probing.
Not a clue about that cdn-cgi access though. Looks like some sort of attack vector, or some sort of misconfigured web service? https://developers.cloudflare.com/fundamentals/reference/cdn-cgi-endpoint/
The part in red i believe has the issue, regex problem. The / needs to be escaped within the regex 'or' match segment.
Code:<IfModule mod_rewrite.c> RewriteEngine On RewriteCond %{HTTP_COOKIE} !xf_user RewriteCond %{REQUEST_URI} ^\/(whats-new|search|members|posts|ams|misc\/cookies) RewriteCond %{HTTP_REFERER} ^https?://([^/]+)(/.*)?$ RewriteCond %{HTTP_HOST} ^%1$ RewriteCond %{REQUEST_URI} ^%2$ RewriteRule ^ - [F,L] </IfModule>
https://regex101.com/r/cdZmI3/1/unit-tests
Not knocking on the solution that you've found... but myself personally, I would rather filter out this abusive scraper stuff at an edge server or intermediate server and never let it reach my actual websites.
Oh, there's a throwback to the early 2000s when folks were getting all up in a bunch that random websites were suddenly blocking incorrect referrer/origins so that they could no longer hotlink images. A few, even as you said, began replacing the image with something very naughty or just throwing a massive "DONT HOTLINK IMAGES FROM OUR WEBSITE!!" as a replacement image. That was a hot-issue for quite some time until image hosts began to pop up then services like AWS's s3 became a thing.
It very likely is. Larger forums (or forums with a lot of history) tend to get slammed very hard.
It's a classic game of whack-a-mole or cat-n-mouse - however you see calling it, it fits the definition. With the right configurations active, ****listing of problematic/toxic ASNs, and expansive 'hair-combing' through access logs, will you be able to get a decent handle on the issue.
It's an ever evolving issue, and it's a matter of time until those script kiddies begin to expand their horizons past Cloudflares bot-blocker stuff. At that point, I'm talking about those same groups finding means and ways to evade and get past Proof of Work tests (Anubis, SafeLine, etc.) and per-server custom created bot-checks (which primarily revolve around basic PoW and captcha variants/implementations). I hope that day doesn't come, but I feel it will in the coming year or two.
Thank you - that is interesting. Botfightmode is certainly doing a lot. But there is a percentage still getting past challenges - even the interactive one.
Bot fight mode covers that already.

One issue was that we had a site in addition to the forum and it wasn't uncommon for others to try to "borrow" our images that we'd scanned and retouched ourselves, most of the time without any attribution. And some of the time, those images were hotlinked from users on the free hosting services that used to exist (remember Geocities?), or the free hosting that came with their ISP account. So they were mostly home-brew sites where the owners didn't know any better, and/or thought they could get something for free with minimal work.Oh, there's a throwback to the early 2000s when folks were getting all up in a bunch that random websites were suddenly blocking incorrect referrer/origins so that they could no longer hotlink images. A few, even as you said, began replacing the image with something very naughty or just throwing a massive "DONT HOTLINK IMAGES FROM OUR WEBSITE!!" as a replacement image. That was a hot-issue for quite some time until image hosts began to pop up then services like AWS's s3 became a thing.
The problem with our older forum (on my oldest site) was that we were on shared hosting and had very little storage space back then. For staff, we had the ability to upload images to a self-hosted gallery and hotlink from there into a forum post, and it was a pain requiring two separate systems and logins. And we couldn't paste in images either.
We have it so good with XF. I'd never go back to those old days, although I'd gladly go back to an Internet without the AI arms race. Back then, Yahoo Slurp! being ill-behaved and hitting us too hard was the worst of our problems!
What baffles me, is that I have about 25+ sites, and the only two that get hit, are both Xenforo forums. Other sites get traffic spikes, but nothing like what the XF ones get. Not even in the same ballpark. IMO, someone is personally targeting XF sites to cause trouble.It's a bit mad the whole thing.

Social media is a gold mine for AI training. It covers so much more than what a brazillion books and static media could deliver: on social media you get a real pulse on the hot topics of the day, the different opinions and conversation styles, the unfiltered use of coloquial language, and so many more little things that have been sterilized from literature or pedantic articles. That's what can make AI seem human and blend in. And then it will be indistinguishable from people, and will be accepted at large.
With a cynical eye, that means the successful replacement of many, many people's jobs with (cheaper) automated tools; it's all about money, and those driving their profits don't care about people's wellfare or that AI will still do far more mistakes while being confidently wrong, as long as people at large accept it passing for a human. AI is not to make humanity's life easier, it is to make a handful of sociopaths much richer.
Just had an internal showcase at work for a call assistant bot that sounds 99% human, can switch to different languages on the fly, remembers pieces of conversation, reacts when interrupted, and so on. It was eerily like a polyglote, all-knowing, seasoned call center person. If this gets rolled out, there's millions of government workers, public administration, clerks of all sorts and basically nearly anyone whose job is primarily to interact with people and process some data, whose last paycheck in that job will be imminent.
And this entire future is based on one thing: consuming as much (relevant) data for statistical model training as possible.
Plus: Forums often have a decade long history and conversations deliver context and connection between topics in a way, that other sources can't. And they are perfect victims: Many forum owners lack technical expertise, lack awareness of the bot issue and even fail to recognize that there is a problem until their forums are massively slow down - they are happy about the visitors, thinking their forum is successful (or they don't look at the metrics at all). With so many older forums being around but neglected by their owners rather than actively managed and updated they are basically what a town full of houses with unlocked front doors would be for a thief. I was pretty baffled how many huge forums only very recently started to take action and how many still didn't.Social media is a gold mine for AI training. It covers so much more than what a brazillion books and static media could deliver: on social media you get a real pulse on the hot topics of the day, the different opinions and conversation styles, the unfiltered use of coloquial language, and so many more little things that have been sterilized from literature or pedantic articles.
regarding the effectiveness of captchas: Here's a recent article that states that they are for the most part increasingly useless against bots:
 unanswered.io
It does however focus more on traditional text or image captchas inc. Google reCapcha and seems to leave out Cloudflare's captcha variants. Nothing really new inside, but still an interesting condensation of the state of things.
Can Bots Bypass reCAPTCHA? Why CAPTCHA Fails in 2026
Bots now solve CAPTCHAs faster and more accurately than humans using AI and cheap human farms. See how reCAPTCHA v3 is bypassed and why traditional tests are no longer reliable.
unanswered.io
It does however focus more on traditional text or image captchas inc. Google reCapcha and seems to leave out Cloudflare's captcha variants. Nothing really new inside, but still an interesting condensation of the state of things.

I was having a similar issue as a lot of members here and opened a different thread because it was mostly META that was killing me and I thought it was a separate issue,
Turned out my simple solution took care of things for me with no addons (I disabled all bot addons) using existing Xenforo tools worked like a charm.
Might work for some of you with the TOO MANY CONNECTIONS error that I had
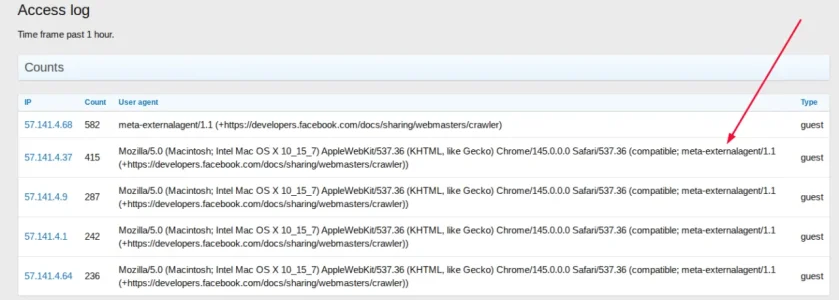
Look at that!!
The top 5 access request on my forum causing the too many connections error are all caused by META
Going to block the meta-externalagent using this extension
Will post back if it made any difference or not.
Turned out my simple solution took care of things for me with no addons (I disabled all bot addons) using existing Xenforo tools worked like a charm.
Might work for some of you with the TOO MANY CONNECTIONS error that I had

Look at that!!
The top 5 access request on my forum causing the too many connections error are all caused by META
Going to block the meta-externalagent using this extension
Will post back if it made any difference or not.
- MapleOne
- Replies: 18
- Forum: Forum management

Maybe because Xenforo is popular and there are a lot of forums and some bot master has decided they are good for scraping - maybe that’s why they know which paths to hit directly - they are familiar with Xenforo.What baffles me, is that I have about 25+ sites, and the only two that get hit, are both Xenforo forums. Other sites get traffic spikes, but nothing like what the XF ones get. Not even in the same ballpark. IMO, someone is personally targeting XF sites to cause trouble.
I had noticed Facebook bot was on a lot but it was the mass of anonymous guests that were the issue on my site. Or are you saying that when you blocked Facebook/Meta a lot of anonymous ones disappeared as well? That would be interesting to try. I am not sure why Facebook would be interested in crawling my forum anyway. It’s not a search engine or scraping for AI - or is it?I was having a similar issue as a lot of members here and opened a different thread because it was mostly META that was killing me and I thought it was a separate issue,
Turned out my simple solution took care of things for me with no addons (I disabled all bot addons) using existing Xenforo tools worked like a charm.
Might work for some of you with the TOO MANY CONNECTIONS error that I had
Look at that!!
The top 5 access request on my forum causing the too many connections error are all caused by META
Going to block the meta-externalagent using this extension
Will post back if it made any difference or not.
- MapleOne
- Replies: 18
- Forum: Forum management
Meta does have an AI for years already (in fact it is one of the most prominent ones: https://ollama.com ) and you can be pretty sure that any of the big tech corps have been grabbing everything they can get their hands on for years to train their AI models (internal or public ones) and still do. You can also be pretty sure that everything you post on any of Metas Platforms (Facebook, Instagram, etc.) is used for AI training. Google does it even with your personal mailbox as long as you do not opt out.I am not sure why Facebook would be interested in crawling my forum anyway. It’s not a search engine or scraping for AI - or is it?
I blockedI had noticed Facebook bot was on a lot but it was the mass of anonymous guests that were the issue on my site. Or are you saying that when you blocked Facebook/Meta a lot of anonymous ones disappeared as well? That would be interesting to try. I am not sure why Facebook would be interested in crawling my forum anyway. It’s not a search engine or scraping for AI - or is it?
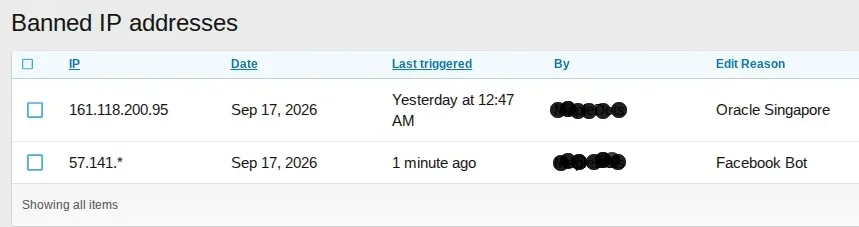
The 57.141.* was taking all my resources for weeks, so I banned the entire facebook/meta ip block and have not had a resource issue once. The singapore IP was not causing a resource issue, I just blocked it because it was affecting my webstats.
Read the link I provided, I also added a 403 Error to the banned phrase.
I am not sure why Facebook would be interested in crawling my forum anyway. It’s not a search engine or scraping for AI - or is it?
Meta externalagent is a bot that is used dedicatedly for AI training. Have a look at the definition that Meta gives about their various bots:
Meta Web Crawlers | Meta for Developers
 developers.facebook.com

The meta-externalagent bot is very intrusive. I blocked it in Cloudflare, together with other AI scrapers.I was having a similar issue as a lot of members here and opened a different thread because it was mostly META that was killing me and I thought it was a separate issue,
Turned out my simple solution took care of things for me with no addons (I disabled all bot addons) using existing Xenforo tools worked like a charm.
Might work for some of you with the TOO MANY CONNECTIONS error that I had
Look at that!!
The top 5 access request on my forum causing the too many connections error are all caused by META
Going to block the meta-externalagent using this extension
Will post back if it made any difference or not.
- MapleOne
- Replies: 18
- Forum: Forum management
I'm on Cloud too and I used to put IP ranges in Discourage mode, redirecting them to some bogus site. Worked very well. Until the big waves started coming in, all with different IP's and from just about every country on earth. When the guest count reached 38,000, I decided to put my site behind Cloudflare. Best thing I ever did.
I hope Andy's add-on will keep things in check for you though.
The meta-externalagent bot is very intrusive. I blocked it in Cloudflare, together with other AI scrapers.
It overshadowed all other traffic combined and personally it gives me great pleasure to ban anything facebook. I don't much care to contribute to their platform in any way. My forum is niche and facebook plays no part in it.
I would be interested to see how many other people are taking abuse from 57.141.*
Similar threads
- Replies
- 6
- Views
- 189


- Replies
- 8
- Views
- 222

