Do you mean "Whats New"? That's where 98% of my bots go - so they can scrape all new posts. I don't know what you mean about deleting the bots? A cloudflare rule to protect the path "what's new" catches a lot of them. But as mentioned by people upthread I think - adding "search" and "members" to the rule for whats-new helps in case they just move to target those as well.English: I received an AdSense traffic warning specifically because of these bots. I do my best to delete them whenever I can. They tend to target the "new messages" tab in particular. I will be taking stricter measures in the future; otherwise, the AdSense warning won't go away.

You are using an out of date browser. It may not display this or other websites correctly.
You should upgrade or use an alternative browser.
You should upgrade or use an alternative browser.
Crazy amount of guests
- Thread starter Levina
- Start date
-
- Tags
- bot swarms guests

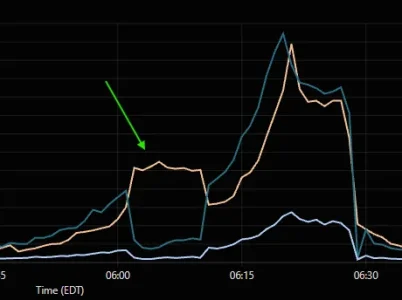
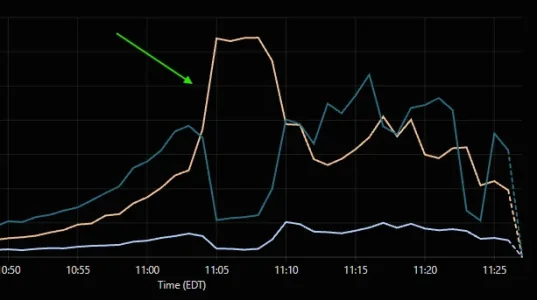
An interesting visual thing I noticed with analytics.
From 6am this morning:
Yesterday around 8pm:
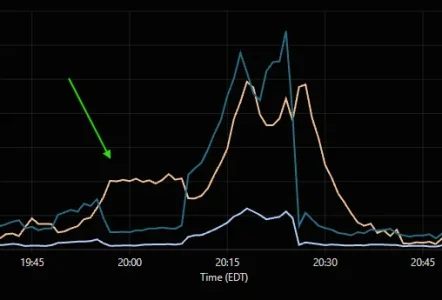
I'm calling it "CF Asleep at the Wheel." It's interesting how the CF caching drops way down while mitigation jumps sharply, before the worst of the bot activity. Almost like something wakes up at CF and catches it...but only for a few minutes apparently.
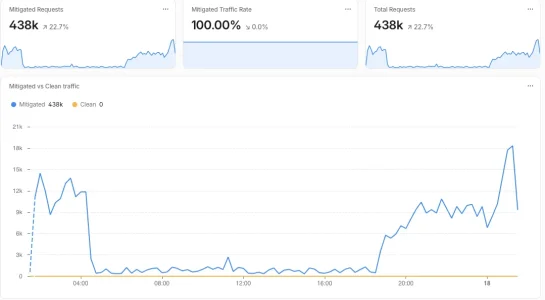
I like seeing incidents like this:
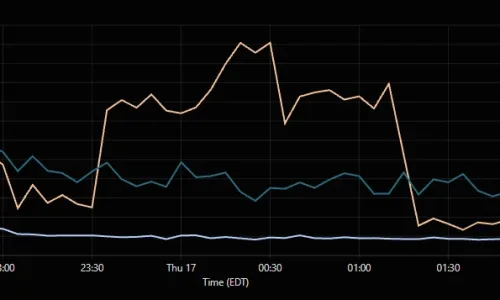
All mitigation, very little effect on normal traffic.
From 6am this morning:
Yesterday around 8pm:
I'm calling it "CF Asleep at the Wheel."
It's interesting how the CF caching drops way down while mitigation jumps sharply, before the worst of the bot activity. Almost like something wakes up at CF and catches it...but only for a few minutes apparently. I like seeing incidents like this:
All mitigation, very little effect on normal traffic.
I spoke too soon  Numbers gone right up again to 1500 - which isn't so bad as long as they don't get up into the 2000's again. Of course they are all coming from my whitelisted countries now - Canada and some Europe. The ones I was avoiding challenging.
English: I received an AdSense traffic warning specifically because of these bots. I do my best to delete them whenever I can. They tend to target the "new messages" tab in particular. I will be taking stricter measures in the future; otherwise, the AdSense warning won't go away.
It's a good time to review your security rules, plus there are new tools as of Sept. 15 to configure bot policies. This is under Security -> Settings, AI Bot Policies. There are three choices for Search and Agent.
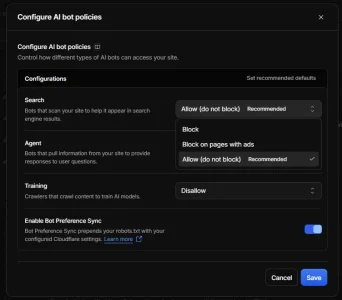
These are then written out to your robots.txt file automatically. (Cloudflare appends its rules to the beginning of robots.txt.)
Sample of the robots.txt alterations (which changes depending on your settings above):
Code:
# As a condition of accessing this website, you agree to abide by the following
# content signals:

# (a)  If a Content-Signal = yes, you may collect content for the corresponding
#      use.
# (b)  If a Content-Signal = no, you may not collect content for the
#      corresponding use.
# (c)  If the website operator does not include a Content-Signal for a
#      corresponding use, the website operator neither grants nor restricts
#      permission via Content-Signal with respect to the corresponding use.

# The content signals and their meanings are:

# search:   building a search index and providing search results (e.g., returning
#           hyperlinks and short excerpts from your website's contents). Search does not
#           include providing AI-generated search summaries.
# ai-input: inputting content into one or more AI models (e.g., retrieval
#           augmented generation, grounding, or other real-time taking of content for
#           generative AI search answers).
# ai-train: training or fine-tuning AI models.
# use:      how AI systems may consume the content (immediate, reference, or full).

# ANY RESTRICTIONS EXPRESSED VIA CONTENT SIGNALS ARE EXPRESS RESERVATIONS OF
# RIGHTS UNDER ARTICLE 4 OF THE EUROPEAN UNION DIRECTIVE 2019/790 ON COPYRIGHT
# AND RELATED RIGHTS IN THE DIGITAL SINGLE MARKET.

# BEGIN Cloudflare Managed content


User-agent: *
Content-Signal: search=yes,ai-train=no,use=reference
Allow: /

# Training crawlers
User-agent: Amazonbot
Disallow: /

User-agent: Applebot-Extended
Disallow: /

User-agent: Bytespider
Disallow: /

User-agent: CCBot
Disallow: /

User-agent: ClaudeBot
Disallow: /

User-agent: Diffbot
Disallow: /

User-agent: Google-Extended
Disallow: /

User-agent: GPTBot
Disallow: /

User-agent: omgili
Disallow: /

User-agent: anthropic-ai
Disallow: /

User-agent: Claude-Web
Disallow: /

User-agent: cohere-ai
Disallow: /

User-agent: MistralAI-Training
Disallow: /

User-agent: meta-externalagent
Disallow: /

User-agent: GoogleOther
Disallow: /

User-agent: Baiduspider
Disallow: /

User-agent: PetalBot
Disallow: /

User-agent: AwarioSmartBot
User-agent: AwarioRssBot
Disallow: /

User-agent: Google-CloudVertexBot
Disallow: /

User-agent: QualifiedBot
Disallow: /

User-agent: Cotoyogi
Disallow: /

User-agent: ICC-Crawler
Disallow: /

User-agent: atlassian-bot
Disallow: /

User-agent: FishBot
Disallow: /

User-agent: BorderxBot
Disallow: /

User-agent: NavuBot
Disallow: /

User-agent: SemrushBot-SWA
Disallow: /

User-agent: WARDBot
Disallow: /

User-agent: magpie-crawler
Disallow: /

User-agent: KimiBot
Disallow: /

User-agent: CitibotSiteCrawler
Disallow: /

# AI Search crawlers
User-agent: PerplexityBot
Disallow: /

User-agent: YouBot
Disallow: /

User-agent: OAI-SearchBot
Disallow: /

User-agent: Claude-SearchBot
Disallow: /

User-agent: Applebot
Disallow: /

User-agent: Amzn-SearchBot
Disallow: /

User-agent: MistralAI-Index
Disallow: /

User-agent: Kimi-SearchBot
Disallow: /

User-agent: ShapBot
Disallow: /

User-agent: Bravebot
Disallow: /

User-agent: Anomura
Disallow: /

User-agent: Element451Bot
Disallow: /

User-agent: alphalens-bot
Disallow: /

# AI Agents
User-agent: Perplexity-User
Disallow: /

User-agent: FireCrawl
Disallow: /

User-agent: FirecrawlAgent
Disallow: /

User-agent: Claude-User
Disallow: /

User-agent: ChatGPT-User
Disallow: /

User-agent: Google-Agent
Disallow: /

User-agent: Google-GeminiNotebook
User-agent: Google-NotebookLM
Disallow: /

User-agent: MistralAI-User
Disallow: /

User-agent: Kimi-User
Disallow: /

User-agent: Amzn-User
Disallow: /

User-agent: meta-externalfetcher
Disallow: /

User-agent: Retool
Disallow: /

User-agent: Instapaper
Disallow: /

User-agent: ChathiveCrawler
Disallow: /

# END Cloudflare Managed ContentAn interesting visual thing I noticed with analytics.
From 6am this morning:
View attachment 344897
Yesterday around 8pm:
View attachment 344898
I'm calling it "CF Asleep at the Wheel."
I like seeing incidents like this:
View attachment 344899
All mitigation, very little effect on normal traffic.
A three-peat:
I've joined the misc/cookies club. As that is not a field in my whats/new, search, members rule, the bots going for misc/cookies (which they weren't before) are bypassing rule 3 but being picked up by the countries rule and getting past that because I whitelisted US Canada and Europe etc. I was googling a bit to see how they can trigger getting a cookie token. Google say (may be incorrect) that even if they can't literally click on the cookie banner, they call the url to make the server think someone has clicked on the cookie banner. Although I do think some of these bots using pupeteer can actually click on things. Regardless of how they do it, it perhaps allows them in with a cookie.
Anyway something else to add - misc/cookies
And also they're now heading for posts/xxxxx/reactions and ams as well - articles page. Have to tweak my rules again.
Anyway something else to add - misc/cookies
And also they're now heading for posts/xxxxx/reactions and ams as well - articles page. Have to tweak my rules again.
Last edited:

Yes, I'm leaving it off too.I feel better leaving it off, vs. hoping a CF rule might catch it. (I still can't trust CF rules 100%.) Visitors can use Google if they want to search the forums. When I do our upgrade, Google search will be in the search drop-down, so that will be available to everyone. Nobody has complained (and with this forum, they'll complain to the owner immediately if they don't like something), so I'm not worried about it.
You can include search in a rule though.
I have a rule for what’s new, search and members - excludes xf_cookie, excludes known bots, referer = **.
So genuine guests and registered members bypass it. Bots get challenged. On the other hand none of my bots are targeting search - they are 98% targeting what’s new. 2% targeting cookies, posts and ams but set up a separate rule for those which has 0% csr rate. I know I could have included that in the what’s new rule but wanted to monitor it .
The big issue IMO is the bots that can solve challenges, use actual real browsers and puppeteer. There is nothing in the Cloudflare free plan to tackle those - other than a hard block - which would be hard to achieve without affecting members and genuine guests.
Which is why my Whats new rule only has a 19% csr. So the bots targeting what’s new are the sophisticated ones (or 19% of them are). The bots targeting other paths all get caught.
I'm not confident CF blocks everything it says it does. Never have been. That is why I disabled search for non-member. I still have the rule in CF should I ever reopen it but, since we've had no complaints, I'm not worrying about it anymore.
Bot are really busy at the moment. Cloudflare is doing good work but can't stop those that view actual content so 1350 guests in the house right now but I'm not particularly worried as all forbidden doors are closed. But 432.63k requests over the last 24 hours. Two big waves.
Cookies still a favourite but CSR is 0.03% for that managed challenge.
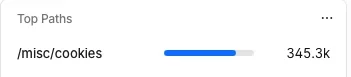
Cookies still a favourite but CSR is 0.03% for that managed challenge.
I don't know what the deal is, but my top path is
/favicon.ico. It's almost double the second top path in the list, which is /cdn-cgi/rum. And that doesn't even exist on our server.
Mitigated requests, which means CF stopped that.But 432.63k requests
Why yes, of course. But the sheer number of requests is crazy high.Mitigated requests, which means CF stopped that.
I don't know what the deal is, but my top path is/favicon.ico. It's almost double the second top path in the list, which is/cdn-cgi/rum. And that doesn't even exist on our server.
I'd assume this is somewhat normal as the favicon is part of every page's source code and typically shown within either the browser tab and/or the browser address line. As it is static it may be cached but with every visitor it is typically requested at least once and if you have a lot of clients that request only one page it will easily be on top of the list.
I do have however some mystery with the variations of favicon.ico and frequent requests for it's possible variations like
/apple-touch-icon-120x120-precomposed.png
/apple-touch-icon-precomposed.png
/apple-touch-icon.png
which I did not manage to solve until now.
Last night I was looking at the bots hammering /misc/cookies, their number one target on my site, looking for commonalities. I found them in the query string. All those strings end in update=1. So I added a new custom rule with a hard block on the combo /misc/cookies and update= (excluding members and known bots). And look at the result:
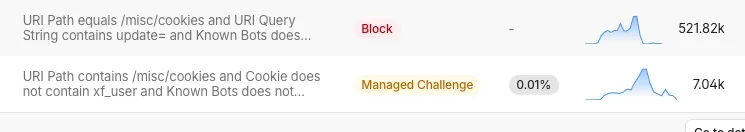
It blocks most of them now so there's relatively few left that move on to the managed challenge.
EDIT: This turned out to block out people when they clicked on the cookies tab, so the exceptions did not work!! I deleted the rule.
It blocks most of them now so there's relatively few left that move on to the managed challenge.
EDIT: This turned out to block out people when they clicked on the cookies tab, so the exceptions did not work!! I deleted the rule.
Last edited:

Well now that I opened this topic, one more important comment/warning. Members are responsible for the contents they post, including any contents from third parties which may be copyrighted. Just because your members found it somewhere and thought it would be cool to share, doesn't mean that somewhere has given them the license to take that (copyrighted) content and post it on your forum. You could be liable for hosting copyrighted content without having an explicit permission from the copyright holder. So make sure you have an educational topic about the responsibilities associated with bringing contents from elsewhere into their replies on your forum, what falls under the acceptable limit for quoting (and giving credit to the source), why hotlinking external content or uploading to your forum attachments that's not their intellectual property (in theory even memes, we're all guilty of that) is problematic, etc. Make sure you have a contact method for anyone who wants to report or claim copyrighted contents.Without going too deep into the legalese of copyright
Could someone give an opinion on the .htaccess code below please (haven't added it yet). After my surge to 1400 in the guest list yesterday, I investigated. Whereas previously, the bots were 99.9% hitting whats new and none of them had a referer, they have upped their strategy and now have added a referer. Had this analysed by Claude which showed they were doing this by mirroring the path they requested to become the referer. And as no genuine guest would ever have a referer like that, there might be a way to block them via .htaccess. So I wondered if someone could take a look at this .htaccess code please. Which blocks any visitor that has the request page as a referer but exempts registered members. I'm not going to blindly add that to .htaccess so an opinion on the code would be appreciated. The code includes other paths as well because there are a small number of bots going to those paths as well and when analysed, they were also faking a mirrored path referer.
I know I could just remove the referer element from the rule and challenge all genuine guests but I'd like to think there was a way of beating the bots and avoiding challenging genuine guests. Also if this did work I could narrow down how many were actually solving the challenge or not. Additionally this would BLOCK them rather than challenging them.
<IfModule mod_rewrite.c>
RewriteEngine On
RewriteCond %{HTTP_COOKIE} !xf_user
RewriteCond %{REQUEST_URI} ^/(whats-new|search|members|posts|ams|misc/cookies)
RewriteCond %{HTTP_REFERER} ^https?://([^/]+)(/.*)?$
RewriteCond %{HTTP_HOST} ^%1$
RewriteCond %{REQUEST_URI} ^%2$
RewriteRule ^ - [F,L]
</IfModule>
Edit - claude thinks it's a self referencing script creating the referer. However I suppose even if this worked they could reprogram the bots to add some different kind of referer as any referer would allow them to pass - but that would take a lot of effort for whoever was behind the bot behaviour presumably?
Edit 2 - I wonder if the same botmaster can read this post on here!
Last edited:
Same here, and the amount is high with those and favicon.ico when we have the larger bot swarms. My only wish (?) is that they are using this along with our forum URL and name as a means of attribution. But it's still an abnormally large number, like double the next in the list.I do have however some mystery with the variations of favicon.ico and frequent requests for it's possible variations like
Our largest forum has been contacted for that reason. Usually it's some obscure photo, by some obscure person nobody has ever heard of, and their emails are usually overboard (along the lines of "take that photo off now, or we're sending in the lawyers") rather than politely asking. We've had other wild requests for members' own post content, yet they take the privacy laws out of context and try to apply them to the forum. We either ignore those, or clarify the laws they are quoting, and we never hear from them again.Just because your members found it somewhere and thought it would be cool to share, doesn't mean that somewhere has given them the license to take that (copyrighted) content and post it on your forum.
Nobody knows how to be nice. If you ask nicely, we'll take something down. Threaten us? We'll make the least amount of effort to comply, and we're not exactly going to rush. (We once had a member whose workplace got ahold of what he might be posting, so he requested that we remove his posts so he didn't lose his SEC license. As he was a good member, we gladly complied, and being on vBulletin at the time, we used Coventry to hide his posts. We had to soft-delete them when we moved to XF.)
We do also encourage members link to an article, and give only excerpts. On one forum, I have an add-on that alters the permissions of the Spoiler BBCode so that only members can view it, so if I'm adding content that I want to keep out of the public eye, this also works. (It is also a good way to drive engagement, as when I write an article, I may sometimes hide the last half of it to entice visitors to join.)
I think we are helping to educate members that pasting in photos or entire articles isn't the right way to post, and most seem to catch on.

Completely eradicated the issue on my forum...no Cloudflare or cumbersome add-on needed. Go over to https://www.xf2addons.com/ Andy has the fix.
Similar threads
- Replies
- 6
- Views
- 189


- Replies
- 8
- Views
- 222

