Thanks.Just add ASN 399358 to your blacklist in the CF filtering rule, that will reject any incoming connection from Anthropic. Optionally use Claude as keyword for identifying and blocking bots, instead of the explicit ClaudeBot / Claude-SearchBot, but that's based on the assumption that the bots will continue to follow the convention to identify themselves.

You are using an out of date browser. It may not display this or other websites correctly.
You should upgrade or use an alternative browser.
You should upgrade or use an alternative browser.
Crazy amount of guests
- Thread starter Levina
- Start date
-
- Tags
- bot swarms guests

For those wanting to block the nasty crawlers in one go, including AI Training, a single CF expression for use.
It will target: meta-externalagent, ClaudeBot, Amazonbot, SemrushBot, DotBot, AhrefsBot, Bytespider, GPTBot, MJ12bot, AcademicBot, ExaSearchBot, ShapBot, PetalBot, meta-webindexer, ReflectionBot, yacybot, LinkupBot, generic “compatible; crawler” user agents, Scrapy, Sogou, Qwantbot, Barkrowler, curl, ClueWeb-Crawler, Turnitin, MathPicDatasetCrawler, PurityBot, img2dataset, quillbot, IbouBot, Go-http-client, Brightbot, Mediatoolkitbot, webzio, YisouSpider, AwarioBot, CCBot, okhttp, serpstat, DataForSeo, Google-Extended, Timpibot, cohere-ai, anthropic-ai, ZoominfoBot, Applebot-Extended, Diffbot, ImagesiftBot, FacebookBot, omgili, BLEXBot and W3C_Validator.
Code:
(http.user_agent contains "meta-externalagent" or http.user_agent contains "ClaudeBot" or http.user_agent contains "Amazonbot" or http.user_agent contains "SemrushBot" or http.user_agent contains "DotBot" or http.user_agent contains "AhrefsBot" or http.user_agent contains "Bytespider" or http.user_agent contains "GPTBot" or http.user_agent contains "MJ12bot" or http.user_agent contains "AcademicBot" or http.user_agent contains "ExaSearchBot" or http.user_agent contains "ShapBot" or http.user_agent contains "PetalBot" or http.user_agent contains "meta-webindexer" or http.user_agent contains "ReflectionBot" or http.user_agent contains "yacybot" or http.user_agent contains "LinkupBot" or http.user_agent contains "compatible; crawler)" or http.user_agent contains "Scrapy" or http.user_agent contains "Sogou" or http.user_agent contains "Qwantbot" or http.user_agent contains "Barkrowler" or http.user_agent contains "curl" or http.user_agent contains "ClueWeb-Crawler" or http.user_agent contains "Turnitin" or http.user_agent contains "MathPicDatasetCrawler" or http.user_agent contains "PurityBot" or http.user_agent contains "img2dataset" or http.user_agent contains "quillbot" or http.user_agent contains "IbouBot" or http.user_agent contains "Go-http-client" or http.user_agent contains "Brightbot" or http.user_agent contains "Mediatoolkitbot" or http.user_agent contains "webzio" or http.user_agent contains "YisouSpider" or http.user_agent contains "AwarioBot" or http.user_agent contains "CCBot" or http.user_agent contains "okhttp" or http.user_agent contains "serpstat" or http.user_agent contains "DataForSeo" or http.user_agent contains "Google-Extended" or http.user_agent contains "Timpibot" or http.user_agent contains "cohere-ai" or http.user_agent contains "anthropic-ai" or http.user_agent contains "ZoominfoBot" or http.user_agent contains "Applebot-Extended" or http.user_agent contains "Diffbot" or http.user_agent contains "ImagesiftBot" or http.user_agent contains "FacebookBot" or http.user_agent contains "omgili" or http.user_agent contains "BLEXBot" or http.user_agent contains "W3C_Validator") and (not cf.client.bot) and (not http.cookie contains "xf_user")It will target: meta-externalagent, ClaudeBot, Amazonbot, SemrushBot, DotBot, AhrefsBot, Bytespider, GPTBot, MJ12bot, AcademicBot, ExaSearchBot, ShapBot, PetalBot, meta-webindexer, ReflectionBot, yacybot, LinkupBot, generic “compatible; crawler” user agents, Scrapy, Sogou, Qwantbot, Barkrowler, curl, ClueWeb-Crawler, Turnitin, MathPicDatasetCrawler, PurityBot, img2dataset, quillbot, IbouBot, Go-http-client, Brightbot, Mediatoolkitbot, webzio, YisouSpider, AwarioBot, CCBot, okhttp, serpstat, DataForSeo, Google-Extended, Timpibot, cohere-ai, anthropic-ai, ZoominfoBot, Applebot-Extended, Diffbot, ImagesiftBot, FacebookBot, omgili, BLEXBot and W3C_Validator.

The two should be unrelated. The big bucket of AI companies' bots identify themselves as such and come from their datacenters. If you filter by source IP/ASN and optionally by user-agent, you can catch them. The other category is what we presume to be bots scraping data for AI training, which hide their nature by offering a regular user-agent identification and coming through residential proxies. The two have in common only their purpose of consuming data for AI models, but the way they achieve that is very different.
There is (at least) one exception: people's facebook/instagram app. Whenever people share a link with someone else, the app on their device wants to "prettify" that link by showing a little snippet below (like it turns Youtube URLs into a preview image of the video). So the app makes a connection to that URL to grab a bit more info, and this is what you'd see in the logs as a connection from someone's personal device that identifies itself as a meta-something. If this connection is blocked, the link in their conversations will appear just like that, a single link without any of that extra info.
There is (at least) one exception: people's facebook/instagram app. Whenever people share a link with someone else, the app on their device wants to "prettify" that link by showing a little snippet below (like it turns Youtube URLs into a preview image of the video). So the app makes a connection to that URL to grab a bit more info, and this is what you'd see in the logs as a connection from someone's personal device that identifies itself as a meta-something. If this connection is blocked, the link in their conversations will appear just like that, a single link without any of that extra info.
It is not that different actually: Both suck, both slurp whatever they can get hold of and both may bombard your forum with requests recklessly w/o any respect, affecting the performance of the forum. The only difference is that one has a logo on the front side of his shirt while the other has not.The two have in common only their purpose of consuming data for AI models, but the way they achieve that is very different.
There is (at least) one exception: people's facebook/instagram app. Whenever people share a link with someone else, the app on their device wants to "prettify" that link by showing a little snippet below (like it turns Youtube URLs into a preview image of the video). So the app makes a connection to that URL to grab a bit more info, and this is what you'd see in the logs as a connection from someone's personal device that identifies itself as a meta-something. If this connection is blocked, the link in their conversations will appear just like that, a single link without any of that extra info.
But this is a different bot (and still one that one may want to block) as has been discussed and mentioned already repeatedly in this thread. Once more we are starting a loop and to discuss again what has already been discussed.
Meta externalagent is a bot that is used dedicatedly for AI training. Have a look at the definition that Meta gives about their various bots:
Meta Web Crawlers | Meta for Developers
developers.facebook.com
This overview about Meta's bots shows the different purposes that their bots have. The one you mean is "FacebookExternalHit". It is however not only used for creating previews for links and the amount I saw in my logs before I blocked it was surprising, given that my forum is barely ever mentioned on one of Meta's platforms. Also, it serves other purposes as well as Meta states and it does not respect robots txt. Almost all of the requests on my forum came from client networks, so this bot is perfect to be used as a fake user agent. All in a lot of arguments to block that thing. The price to pay is that you may not have a link preview on Meta's platform - something I can easily live with.
It is called "the internet" and as long as you are not ruling it anybody can visit any site whenever he or she wants w/o your permission.Well the bots have just dropped down from 1200 to 300 again in the guest list, 24 hours later, without me doing anything. So must have been a swarm. Not nice they can just do it whenever they feel like it, despite all my rules.


That is what I am thinking also. Forum owner is in Los Angeles, the staff member who sees the issue infrequently is in Iowa, and I'm even further east. CF's own VPN service seems to have a connection in the closest big city to us, but I don't know if that means there is a Cloudfront instance near us (where the closest might be Chicago).While not cloudflare, AWS's Cloudfront in Kansas City (Tagged as MCI) has been giving me constant fits with https://www.spc.noaa.gov/ when the SPC auto-pushes out updates to their site. Site hangs, nothing rendering, missing content on render, etc. Using my VPN server in Chicago, which routes to the Chicago AWS S3/CF origin - no issues.
I honestly think all the bad bots raid robots.txt just to sniff out directories we don't want them to visit. These days I just assume that robots.txt is only there for bots that respect it, and the rest I need to handle in CF.At least they're querying robots.txt now... i guess? They don't seem to respect it though.
Absolutely. I have had the ASNs of those corporations that build only AI products blocked in our rules. What I can't block, like Google's multi-purpose bots, I use robots.txt and hope that Google respects those. (And CF has the tool to handle that.)Just add ASN 399358 to your blacklist in the CF filtering rule, that will reject any incoming connection from Anthropic.
I mean, it's pretty clear that I effing hate AI. I absolutely refuse to use it, and have compiled a long list of over 100 links to articles demonstrating how harmful it is to the society, the economy, the environment, and human rights (look at what Flock offers for police departments, who are using the AI Flock provides to wrongfully track and arrest innocent people). I'm actually preparing a multi-part article for the magazine I write for, so this is all part of information gathering. AI is nothing any of us asked for, and nothing we need in our lives. It's there to feed more tens of billions of dollars to the oligarchs in this world, and keep the shareholders happy.
These waves of bot attacks from the AI arms race, which are stealing valuable hours of life from all of us here, is right up there with one of AI's harms to society. For most of us, this is all unpaid work, just having to defend our servers (either for clients, and ourselves). Between monitoring our own traffic, adjusting rules, and having to read this thread along with countless other sources of information to try to make sense of it all, it's a giant time suck. And none of us are getting that time back.
That is a pretty interesting ASN btw:Just add ASN 399358 to your blacklist in the CF filtering rule, that will reject any incoming connection from Anthropic.
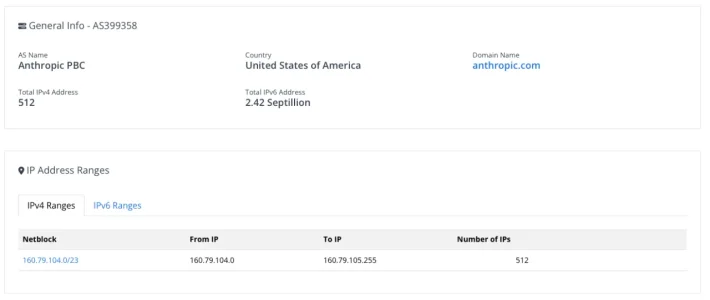
Just 512 IP V4 addresses but 2,42 Septillion IP V6 addresses.
 And they do have a direct peering with Cloudflare.
It is certainly taking time away from us - but - are the residential proxies the same as the AI crawlers? To me the issue has been the residential proxies. I'm sure a lot of them ARE some kind of AI crawler, but some may be something else altogether or more sinister and criminal.That is what I am thinking also. Forum owner is in Los Angeles, the staff member who sees the issue infrequently is in Iowa, and I'm even further east. CF's own VPN service seems to have a connection in the closest big city to us, but I don't know if that means there is a Cloudfront instance near us (where the closest might be Chicago).
I honestly think all the bad bots raid robots.txt just to sniff out directories we don't want them to visit. These days I just assume that robots.txt is only there for bots that respect it, and the rest I need to handle in CF.
Absolutely. I have had the ASNs of those corporations that build only AI products blocked in our rules. What I can't block, like Google's multi-purpose bots, I use robots.txt and hope that Google respects those. (And CF has the tool to handle that.)
I mean, it's pretty clear that I effing hate AI. I absolutely refuse to use it, and have compiled a long list of over 100 links to articles demonstrating how harmful it is to the society, the economy, the environment, and human rights (look at what Flock offers for police departments, who are using the AI Flock provides to wrongfully track and arrest innocent people). I'm actually preparing a multi-part article for the magazine I write for, so this is all part of information gathering. AI is nothing any of us asked for, and nothing we need in our lives. It's there to feed more tens of billions of dollars to the oligarchs in this world, and keep the shareholders happy.
These waves of bot attacks from the AI arms race, which are stealing valuable hours of life from all of us here, is right up there with one of AI's harms to society. For most of us, this is all unpaid work, just having to defend our servers (either for clients, and ourselves). Between monitoring our own traffic, adjusting rules, and having to read this thread along with countless other sources of information to try to make sense of it all, it's a giant time suck. And none of us are getting that time back.
Edit - and stealing written articles as well .....................
Last edited:
Wow...
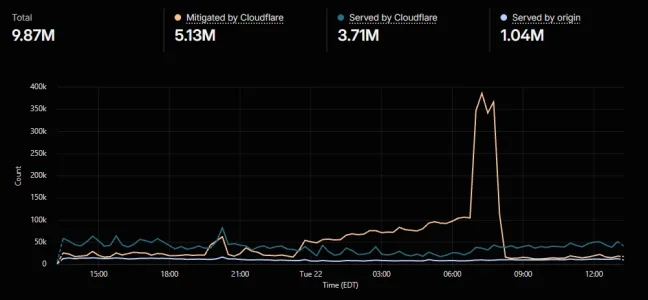
Another 24 hour snapshot. Enormous spike in activity this morning, but we cruised along without a single blip.
Cloudflare pulling its weight! This is the highest 15-minute period.
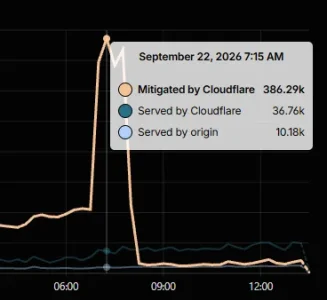
386k vs. 10k? Yeah. I'll take it.
Another 24 hour snapshot. Enormous spike in activity this morning, but we cruised along without a single blip.
Cloudflare pulling its weight! This is the highest 15-minute period.
386k vs. 10k? Yeah. I'll take it.
And those IPv6 addresses are in two blocks, apparently:Just 512 IP V4 addresses but 2,42 Septillion IP V6 addresses.
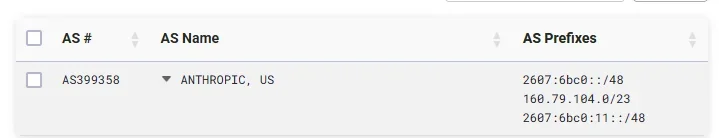
Why would anyone need that many IP addresses allocated to them?
Wild guess - they have some sort of CI/CD pipeline that runs in iterative cycles to assemble automatically thousands of instances of AI models for slightly different datasets and configuration parameters, which they test at scale and then retain only those variants that fulfill criteria, the rest are scrapped. Even what seems to be a single AI model available for public consumption could actually be made out of tens of thousands of computing nodes, each with its own IP.

Scaling out massive amounts of scrapers, instances, etc. It's not too uncommon seeing huge IPv6 CIDR's being delegated out like candy... just going to end up with the same ipv4 crunch for ipv6 in a century or two down the road.Why would anyone need that many IP addresses allocated to them?

Oh heck my bots are back up to 1600 again tonight. I'm almost tempted to unblock Claudebot and see if they go down again. I wonder if it's to do with the new rule created by Cloudflare AI crawl control. When you click to block AI bots on that, it automatically creates a new custom block rule. It placed it at the end of my rules. As it was a block rule I thought it should go higher up with the other block rule, above my challenge rules, so moved it.
969,000 bots hitting Cloudflare/the site at the moment. 597,000 mitigated by Cloudflare
969,000 bots hitting Cloudflare/the site at the moment. 597,000 mitigated by Cloudflare
Last edited:
That is exactly what I was saying in another forum where I posted this same information--IPv6 was developed to overcome the limited number of IP addresses in IPv4. 2,420,000,000,000,000,000,000,000 is...an incredibly greedy number. I blame Anthropic as much as I do whichever organization allowed that many IP addresses to be assigned. A septillion is a trillion trillions.It's not too uncommon seeing huge IPv6 CIDR's being delegated out like candy... just going to end up with the same ipv4 crunch for ipv6 in a century or two down the road.
Google AI suggested that some of these bots were faking being Claudebot, so when I blocked Claudebot, they proliferated elsewhere. Not sure it that's a thing or not. But, Claudebot had started hitting register and /register is disallowed in robots.txt - and Claudebot is supposed to respect robots.txt. So maybe it actually is other bots pretending to be Claudebot.
Either way I'm not unblocking Claudebot until the guest numbers go down - can't risk them going any higher again.
So is it better to block Claudebot in robots.txt rather than at Cloudflare level?
Either way I'm not unblocking Claudebot until the guest numbers go down - can't risk them going any higher again.
So is it better to block Claudebot in robots.txt rather than at Cloudflare level?

You're better off going through your own internet security software that should have something similar to what Cloudflare has when it's under attack mode.1800 now. So all this work the last three weeks and the numbers are right back up again.
That way it puts all of it's energy into stopping bots that are DDOSing your forum
No. Block the ASN, as someone posted above. Remember robots.txt can only suggest, it can't block. The user-agent strings can also be blocked (or challenged), for other bots giving false user-agent strings.So is it better to block Claudebot in robots.txt rather than at Cloudflare level?
Similar threads
- Replies
- 6
- Views
- 189


- Replies
- 8
- Views
- 222

