Crazy amount of guests

My previous post does this, a better way IMO, using cf.client.bot: ((http.user_agent contains "Googlebot" or http.user_agent contains "bingbot" or http.user_agent contains "Applebot" or http.user_agent contains "DuckDuckBot" or http.user_agent contains "Google-InspectionTool" or http.user_agent contains "Mediapartners-Google" or http.user_agent contains "AdsBot-Google" or http.user_agent contains "YandexBot" or http.user_agent contains "Baiduspider") and (not cf.client.bot))
I do it similarly myself. 👍 I shorten/combine some of them, similar to lower(http.user_agent) contains "google".
I'm going to try that, thanks.
 
I think I will take a break from this thread. It is absolutely fine if you like it as it is - I more and more don't, it has lost it's value for me for the most part. Absolutely not worth participating here any more at the moment.
Good, because your complaining doesn't help anyone either.
 
Good, because your complaining doesn't help anyone either.
Obviously not, if there is no change in behavior. At the moment you are shooting the messenger: I am in sorrow about the quality of the discussion, the reliability of the information within this thread and the usefulness of the thread for other, especially less experienced forum members and try to create awareness for the problem I see. You are not or don't see the problem (or don't care) and instead start to attack me on my "high horse". Which is exactly why I drop out of the discussion. We will see where this thread turns to and ends up, one way or another.
 
Last edited:
Maybe this thread became a mix of different conversations, and might help to be split up moving forward, for clarity.

On one hand, we need to have a deep technical conversation about how this space evolves, what different people experienced, what they tried and what worked - all new knowledge intended for the common use.

Eventually that know-how should be condensed in some sort of "good practice" or tl;dr for those who have the same problem but do not have the time, capability or interest to deep dive into all of this, and just want some relatively simple to follow steps to solve the problem and move on with their lives.

On the other hand, there will be multiple cases of individual support requests, each with its own thread focusing solely on reapplying the existing good practice on their own forum. That's the kind of conversation that might be perceived as "noise" when mixed with the former.
Something something wiki-style editing of original posts within threads. ;)

But you're right, might be time to split-down this this thread into resources, discussion, research/findings. We're at 82 pages now... 1,625 posts!
 
It was already 60 pages long when I joined it with an issue. A lot of people are having the same issues out of the blue.
 
My previous post does this, a better way IMO, using cf.client.bot: ((http.user_agent contains "Googlebot" or http.user_agent contains "bingbot" or http.user_agent contains "Applebot" or http.user_agent contains "DuckDuckBot" or http.user_agent contains "Google-InspectionTool" or http.user_agent contains "Mediapartners-Google" or http.user_agent contains "AdsBot-Google" or http.user_agent contains "YandexBot" or http.user_agent contains "Baiduspider") and (not cf.client.bot))
Assume I could add Facebook and Twitterbot to this? I have a fake one at the moment in the robots list that claims to be both Facebook and Twitterbot (and it's neither).
 
Obviously not, if there is no change in behavior. At the moment you are shooting the messenger: I am in sorrow about the quality of the discussion, the reliability of the information within this thread and the usefulness of the thread for other, especially less experienced forum members and try to create awareness for the problem I see. You are not or don't see the problem (or don't care) and instead start to attack me on my "high horse". Which is exactly why I drop out of the discussion. We will see where this thread turns to and ends up, one way or another.
Some of us are fighting a daily battle here and appreciate the advice and help of experts and non-experts alike - in similar situations. Perhaps if a different level of discussion is required that could be a different kind of thread, although personally I don't see why there can't be different degrees of conversation in one thread - people can learn and discuss as well as get urgent advice. However long essays attacking other members aren't helpful to anyone. I believe you yourself pointed people towards this thread (including myself) when they were starting posts because they were having serious issues with bots.

I understand you don't like Cloudflare, but many people are using it.
 
Last edited:
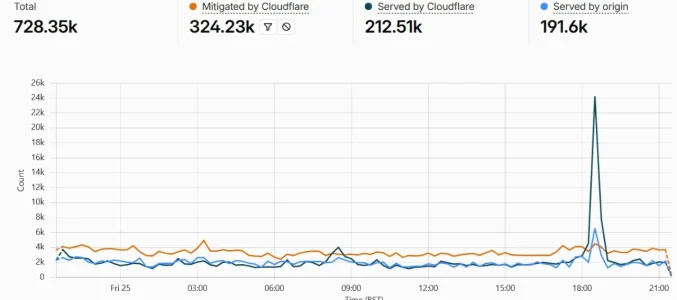
So my problem now is the rising CSR for my whats-new challenge rule - which is now over 30%. And this graph.

Statistics 25.9.webp

Usually the orange mitigated line is at the top - way higher. Numbers in the guest list aren't that high, but the fake robots are presumably scraping. Along with the 30% of bots that solve the challenges. I assume if I block the fake robots I'll get another swarm of global residential proxies.

So the CSR has slowly risen from 18% (where it had been steady for some time) to 30% plus over the past 2 or 3 days. And if it keeps increasing at this rate, the rule will catch very little.

So then where do you go? If bots can solve the cloudflare rule challenges? Bearing in mind these particular ones are using full/real browsers.
 
Last edited:
Maybe this thread became a mix of different conversations, and might help to be split up moving forward, for clarity.
I think we would end up with two similar threads. It's the nature of the beast.

If we could reach a consensus about certain basics and somehow add it to my opening post, that would be great. I can't edit it, but maybe staff would be willing to help.
 
I think we would end up with two similar threads. It's the nature of the beast.

If we could reach a consensus about certain basics and somehow add it to my opening post, that would be great. I can't edit it, but maybe staff would be willing to help.
How nice would it be to have a built-in wiki-style collaborative thread and not an addon to do such? :P

We're quite a bit off topic now, but I still do agree that we need to collect all items of note thus far when dealing with Abusive AI Scraper Botnets / Abusive & Toxic bots, slapping it into a central location. No one is going to want to dredge thru 80+ pages to find a simple answer, less the fact of any pros and cons.
 
I'm going to try that, thanks.
If you're using previously posted rules from me, that is already in one of them. I had somewhere between 90k to 150k per hour for the last 24hrs... they haven't been near me for a while now, no impact, and it seems the majority were fake browsers, as they got caught in the first rule: (((http.user_agent contains "Chrome/1" and not any(lower(http.request.headers.names[*])[*] == "sec-ch-ua"))) or (((http.user_agent contains "Mozilla/5.0" and (http.user_agent contains "Chrome/1" or http.user_agent contains "Firefox/1")) and not any(lower(http.request.headers.names[*])[*] == "sec-fetch-mode"))) or (((http.user_agent contains "Mozilla/5.0" and (http.user_agent contains "Chrome/1" or http.user_agent contains "Firefox/1")) and not any(lower(http.request.headers.names[*])[*] == "accept-language")))) and (not cf.client.bot) and (not http.cookie contains "xf_user")
 
For those blocking ASNs: There is a new kid on the block:

AS5065 (Bunny Communications)

Quite a bunch of IPs from that ASN turn up very frequently in my logs since yesterday or the day before yesterday. The ASN is multinational, labeled as "corporate". The IPs in my log are from various locations in the US and there is absolutely no reason why all of a sudden s/o using this ASN should have such intense interest in my forum and even less so as I only have a single digit number of regulars from the US. All of the IPs I saw in my logs and checked have at least one complaint at ipsearch.io, i.e. https://ipsearch.io/ip-lookup/?ip=209.101.57.85

The requests were all single requests, targeting URLs uncommon for a genuine user (let alone as single request) and were using a wonky user agent like i.e.

209.101.57.85 - - [26/Sep/2026:09:49:34 +0200] "GET /posts/10143/reactions HTTP/1.1" 200 2089 "-" "Mozilla/5.0 (Linux; Android 14; 23127PN0CC) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/147.0.0.0 Mobile Safari/537.36" 2436 10073

207.97.154.229 - - [26/Sep/2026:10:45:28 +0200] "GET /goto/post?id=13783 HTTP/1.1" 200 2086 "-" "Mozilla/5.0 (iPhone; CPU iPhone OS 18_6 like Mac OS X) AppleWebKit/605.1.15 (KHTML, like Gecko) CriOS/150.0.0.0 Mobile/15E148 Safari/604.1" 2419 10070

207.97.179.118 - - [26/Sep/2026:10:45:24 +0200] "GET /misc/style-variation?t=1783500338%2C07e89fb9e76969fe594acc645f54a1bd&variation=alternate HTTP/1.1" 200 2161 "-" "Mozilla/5.0 (iPhone; CPU iPhone OS 18_4 like Mac OS X) AppleWebKit/605.1.15 (KHTML, like Gecko) CriOS/151.0.0.0 Mobile/15E148 Safari/604.1" 2585 10145


So it seems that this ASN is new to the game and somewhat eager to build up a negative reputation. A candidate well worth blocking flat out.
 
Here's something that surprised me.

I have 3 custom rules plus the AI Crawl Control rule that is automatically generated if you start blocking AI scrapers in AI Crawl Control, so 4 custom rules in all.

I don't block countries or ASN's. I block bad bots and bad paths. And I have a managed challenge for paths I can't block, such as /whats-new/ /misc/cookies /search/ etc.

Bots went after /misc/cookies the most. Just hammering it. It was the most requested path. So I put /misc/cookies in its own custom rule, removing it from the existing rule, so I could monitor it better. I didn't really find out anything I didn't already know, so after a week or so I put it back with the others and removed the extra rule. And to my surprise /misc/cookies is not being hammered anymore. It moved down the list. Looking at the most targeted path it's now at #10. That was unexpected. It seems to indicate that the order within custom rules also matters. /misc/cookies was first in the rule until I took it out. Putting it back in, it is now at the bottom. Does that make sense at all?
 
It seems to indicate that the order within custom rules also matters. /misc/cookies was first in the rule until I took it out. Putting it back in, it is now at the bottom. Does that make sense at all?
Don't know about Cloudflare but typically Firewall rules work from top to bottom, one after the other. Which in your case means/would mean: It was hit first, so basically all traffic had to pass this rule before coming to the second one. Now it is last, so it only gets hit by the traffic that has not been mitigated/blocked by any of the rules further up.

On common firewalls the order of the rules can be quite important: For one to not shoot you in the foot and secondly, to not grind performance to a halt and eat up too many resources of the firewall by an unlucky rule order.
Yes, I'm well aware of that but you missed that I was talking about the order within a custom rule, not the order of the custom rules themselves.
 
Last edited:
I found that the order of the rules themselves makes a difference. Given what I was blocking (challenging), simply swapping my #2 and #3 rules led to this week of calm we've had on the server. Other than that huge spike, the bots have mostly stayed away. But I'm sure we'll have another swarm before long.

Yes, I'm well aware of that but you missed that I was talking about the other within a custom rule, not the order of the custom rules themselves.
It may depend how they are written also. If a rule is nothing but OR statements, it may not matter. But once we mix OR and AND, things get...interesting. 😂

One issue I've had is that once I start nesting parentheses, I have to paste the rule elsewhere to edit it so I can have room to epxand all the rules and see what is actually happening. I've found a few errors that way.

The biggest issue I have right now, which nobody seems to know a way to solve, is that the R2 buckets don't load images/avatars for even logged-in members if I use one of my rules. And I know of no way to whitelist them.
 
Yes, I'm well aware of that but you missed that I was talking about the other within a custom rule, not the order of the custom rules themselves.
I'd assume that within a rule criteria is also worked on serially. So if your baddies are now caught earlier within that rule the URL is no longer looked at. Typically the first rule/criteria that leads to a drop or reject ends the game, whatever comes later does not come into play.
 
I'd assume that within a rule criteria is also worked on serially. So if your baddies are now caught earlier within that rule the URL is no longer looked at. Typically the first rule/criteria that leads to a drop or reject ends the game, whatever comes later does not come into play.
You're not on Cloudflare. Don't assume things.

Brings to mind this:
This is a perfect example of the Dunning-Kruger effect and it does cause harm.
 
I also observed some oddities in the way rules work on CF, especially some that are more complex, with branches or groups of logical operators. For example, I have a list of about 100 ASNs being blocked - not the thousands in various blocklists on the internet but still a bunch organically grown for my domain - and whenever I use "ASN Num in [long list]" it just doesn't seem to be working. But if I split it down in chunks of maybe 20 ASNs and use "ASN Num is in [group 1] OR ASN Num is in [group 2] OR ASN Num is in [group 3]" etc. then it works. What? Why? I don't get it. It probably works better if I define a custom list of ASNs, but that feature is reserved for paying customers.
 
Back
Top Bottom