Thank you that is really helpful. I think I'll have a breather now the Cloudflare rules are working and hopefully the numbers will stay down.Feel free to DM me your servers real IP address behind the Cloudflare route. I can poke about and do some checks on my end.
From visiting your main sites landing page:
Code:alt-svc h3=":443"; ma=86400 cache-control private, no-cache, max-age=0 cf-cache-status DYNAMIC cf-ray a39a74a85dee4e03-MCI content-encoding zstd content-type text/html; charset=utf-8 date Fri, 11 Sep 2026 23:29:38 GMT expires Thu, 19 Nov 1981 08:52:00 GMT last-modified Fri, 11 Sep 2026 23:29:38 GMT link </js/xf/preamble.min.js?_v=bca7a5c7>;as=script;rel=preload,</css.php?css=public%3Anormalize.css%2Cpublic%3Afa.css%2Cpublic%3Acore.less%2Cpublic%3Aapp.less&s=7&l=1&d=1788151970&k=fd9e20032971303b8e578efcfbaa6b5336d21a94>;as=style;rel=preload,</js/sv/lib/link-post.min.js?_v=bca7a5c7>;as=script;rel=preload;fetchpriority=low,</js/vendor/vendor-compiled.js?_v=bca7a5c7>;as=script;rel=preload;fetchpriority=low,</js/xf/core-compiled.js?_v=bca7a5c7>;as=script;rel=preload;fetchpriority=low,</css.php?css=public%3Anotices.less%2Cpublic%3Arating_stars.less%2Cpublic%3Astructured_list.less%2Cpublic%3Axa_ams.less%2Cpublic%3Axa_ams_tile_view_layout.less%2Cpublic%3Axb.less%2Cpublic%3Aextra.less&s=7&l=1&d=1788151970&k=c16eedd134103f725983cb8c6b6670789b0d1fad>;as=style;rel=preload;fetchpriority=low nel {"report_to":"cf-nel","success_fraction":0.0,"max_age":604800} report-to {"group":"cf-nel","max_age":604800,"endpoints":[{"url":"https://a.nel.cloudflare.com/report/v4?s=6RAGHipMc4H%2FyCx3WKwUA4i5luGlovzfrD8rKEiBBq8YT5105evTDmSp0RSPD4wYHedMqts%2FRjuIGfiQbYOdKdgU5wGAgUjGc3%2FJzcZ6bnZiCu%2BiCNjBsj1g897q2TKjf7zinB54G7ndEb83jDOhQwReHF7AaA%3D%3D"}]} server cloudflare server-timing cfCacheStatus;desc="DYNAMIC" server-timing cfEdge;dur=3,cfOrigin;dur=338 vary Accept-Encoding,User-Agent x-content-type-options nosniff x-frame-options SAMEORIGIN x-turbo-charged-by LiteSpeed
Cloudflare is indeed functional. I don't see any leakage from a glance.

You are using an out of date browser. It may not display this or other websites correctly.
You should upgrade or use an alternative browser.
You should upgrade or use an alternative browser.
Crazy amount of guests
- Thread starter Levina
- Start date
-
- Tags
- bot swarms guests
Well it seems I slightly underestimated the scale of the bot attack. As things seemed back to normal and I have all my rules blocking and challenging things, I thought maybe I can turn botfight mode off now. I wasn't actually sure what it was doing so filtered the Cloudflare events to see and it is blocking masses of stuff - AWS, Alibaba, Microsoft - loads of bots with http1 and python in the user agent name. So I think I'll have to leave it on. I was hoping they would just go away!

Eventually they might, when they discover that the effort for scraping vs the limited data they're getting is not worth it. Be patient.
Also, AI can very easily and frequently be confidently wrong. All that blabla about images not working seems completely inaccurate and easily proven so.
But the reason why AI could be so upset about access to images might be because many AI models scrape images and attachments as well. Facebook was hitting my forum incessantly looking for attachments directly, because they do image recognition. For years they have been doing it on photos uploaded by people on their fb accounts even before AI was such a thing, and the surprise came one day when, hidden in the page, photos started to have text descriptions like "older man and young girl holding hands and walking on the beach at sunset". Then the number of people using fb started dwindling, but fb's appetite for training material was not nearly done, and they started scraping the internet. And fb is not the only one; how else do you think Google Lens can look at a photo of a little mound of dried earth sticking up among grass blades on my lawn and go "yup, that's earthworm poop, it's safe, congrats, you have a very healthy and aerated lawn"? (Just happened yesterday.)
Side note - if your forum's attachments are starting to build up on your webhost against your contractual quota, and you're already onboarded on CloudFlare, you might as well enable R2 cloud storage in CF and use the CloudFlare plugin to integrate it in your forum. The attachments will move to CF and free up your host, and the traffic limits for the free tier are very generous. I received an invoice just once, when I did many many many file operations at once (during migrating attachments from my host to R2), and it costed me $0.03 .
[later edit] I fully believe that restricting guests' access to (large) attachments and full size photos is a very reasonable defense of your hosting bill and of the misuse of your forum's (copyrighted) content. Thumbnails should be enough for a legitimate visitor.
Last edited:
Also, being able to see full size images is an incentive for visitors to sign up with an account and become "official" members that sooner or later may start posting and participating in discussions as well. Clearly, not showing full size images to guests (inc. search engines and bots) helps to keep traffic under control as well as to protect copyright and privacy of your users.[later edit] I fully believe that restricting guests' access to (large) attachments and full size photos is a very reasonable defense of your hosting bill and of the misuse of your forum's (copyrighted) content. Thumbnails should be enough for a legitimate visitor.
Absolutely. As said before: @Alvin63 seems overconfident to what an AI says and also overconfidently feeds non public data into the AI which may not be the best idea as this private data may then be used for the training of the AI and even end up in someone else's Ai output. See i.e.Also, AI can very easily and frequently be confidently wrong. All that blabla about images not working seems completely inaccurate and easily proven so.

Chinese AI labs secretly used millions of Claude exchanges to train their models, Anthropic says | CNBC Africa
Anthropic said it detected and disrupted unauthorized large-scale efforts by China-based AI labs including Alibaba, Moonshot and DeepSeek to train their models using Claude. The U.S. AI company said in a threat intelligence report released Thursday that the firms were involved in what it...
 www.cnbcafrica.com
You seem possibly to somewhat misunderstand what ASNs are and how they work. ASNs are a set of networks/IP.-addressess that can span through a lot of countries, so they are not tied to one country. Also, an organization may have multiple ASNs. Some (and possibly Vodafone is such a case) do have ASNs per country (which makes sense for their mobile network).Just a tip for anyone else blocking ASN's in various countries - assuming this hasn't already been mentioned before.
Starlink's main global ASN is 14593 - it could show up in various countries (including Guyana and Myanmar). Also 397763 and 53348.
So Starlink Whitelist is those three.
Some that show up are for Mobile networks like Vodafone (India) 38266 and Orange (Tunisia) 37492 so I think it's important not to block those ASN's as maybe they could affect globally as well?
In fact a lot of the multinational ASNs that will show up in your logs are absolutely worth blocking as nothing but bots come from there. I.e. AS9009 (M247 Europe SRL), AS51809 (HostRoyale Technologies Pvt Ltd), AS203020 (also HostRoyale Technologies Pvt Ltd), AS132203 (TENCENT-NET-AP Shenzhen Tencent Computer Systems) and many others span through many countries and are notorious for scraping and nothing else.
I had quite a bunch of scraping bots coming through starlink btw. as well, possibly residential proxies. So I would clearly challenge starlink.

Looks like a site that I lurk on from time to time has finally met our "AI Botnet Scraper overlords". 
They're using SMF, not XenForo in this instance, but this is probably one of the larger AI floods that I have seen in recent memory:
I don't know what exactly that they've implemented in attempt to fight the issue... but whatever they're doing, doesn't seem to be working at all. From the thread alone, it seems to indicate that the server admin is implementing captcha validation checks against swaths of ISP IP ranges or via CC matching(?)... directly on the forum itself.
They seriously need to implement an external mechanism that doesn't reside on the forum itself. I don't see Cloudflare in any of the headers, or anything else to indicate any sort of security check.
Getting a lot of "502 Bad Gateway" errors - Page 1
Getting a lot of "502 Bad Gateway" errors - Page 1
www.eevblog.com
They're using SMF, not XenForo in this instance, but this is probably one of the larger AI floods that I have seen in recent memory:
I think their SMF is set to 60 minutes for the online cutoff.Most Online Today: 356228. Most Online Ever: 356228 (Today at 07:13:33 am).
I don't know what exactly that they've implemented in attempt to fight the issue... but whatever they're doing, doesn't seem to be working at all. From the thread alone, it seems to indicate that the server admin is implementing captcha validation checks against swaths of ISP IP ranges or via CC matching(?)... directly on the forum itself.
They seriously need to implement an external mechanism that doesn't reside on the forum itself. I don't see Cloudflare in any of the headers, or anything else to indicate any sort of security check.
In regards to Starlink it's kind of in a unique situation. Their IPv4 space is all CGNAT. Then, those IPv4 addresses within ASN 14593 are routed to different parts of the globe. Check this page: https://geoip.starlinkisp.net/feed.csv - Search "Kansas City", "Buenos Aires", or even "Kuwait City".I had quite a bunch of scraping bots coming through starlink btw. as well, possibly residential proxies. So I would clearly challenge starlink.
CGNAT on a massive scale poses a difficult situation when it comes to figuring out what is going on. For example, I might be on 153.66.204.123 for 30 minutes, and then an IP rollover happens and then i am on 153.66.204.231 (Kansas City IP example). But that is just me alone... sharing that same IP address with hundreds of other subscribers in the same region using that PoP. So it's worth keeping in mind that challenging Starlink as a whole might be counter to the desired outcome.
As for their IPv6 space, everything is getting their own unique address - as it should be, but shares the same network design as their IPv4 network: segmented CIDRs to each of their PoPs.
PM the admins with a link to this thread and a tl;dr to start tunelling traffic through some filtration system at transmission (IP) level before it hits their forum software. Anubis, CloudFlare, whatever they fancy. Captcha won't do more than a flea's fart.They seriously need to implement an external mechanism that doesn't reside on the forum itself
Looks like they implemented Cloudflare and some other provider today. Their forums are back to normal speeds.Looks like a site that I lurk on from time to time has finally met our "AI Botnet Scraper overlords".
Getting a lot of "502 Bad Gateway" errors - Page 1
Getting a lot of "502 Bad Gateway" errors - Page 1www.eevblog.com
They're using SMF, not XenForo in this instance, but this is probably one of the larger AI floods that I have seen in recent memory:
I think their SMF is set to 60 minutes for the online cutoff.
I don't know what exactly that they've implemented in attempt to fight the issue... but whatever they're doing, doesn't seem to be working at all. From the thread alone, it seems to indicate that the server admin is implementing captcha validation checks against swaths of ISP IP ranges or via CC matching(?)... directly on the forum itself.
They seriously need to implement an external mechanism that doesn't reside on the forum itself. I don't see Cloudflare in any of the headers, or anything else to indicate any sort of security check.
Just goes to show how devastating these bots can be to anyone's infrastructure.

I'm trying a rather radical (yet very simple) "nuclear option" rule, which I mentioned earlier in the thread to see if we get any complaints and so far, it's working. Our visits are back to pre-bot levels, with guests at most 2x as many as logged-in members, and not one single complaint about not being able to access us. All are non-interactive challenges. Once I get a week or two of using the rule, I'll be able to report back to this thread with pros and cons.Just goes to show how devastating these bots can be to anyone's infrastructure.
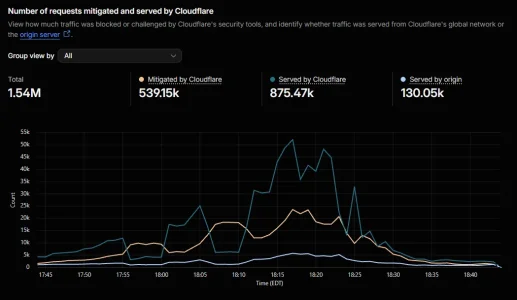
But insofar as "devastating" goes, check this out. We had a spike in traffic today within an hour's time early this evening, and our server loads spike a little--we were never offline (like a "bot DOS" attack could do).
Just the basic stats tell a story of how Cloudflare's intervention helped the forum for a short time, vs. getting absolutely slayed by the inrush of bots. Served by origin--only 130k, out of 1.54M total. Not noly were 539 mitigated, the rest were served from CF's cache (875k). So the cache plus the mitigation stepped up to keep us running. And I was just tihnking this past week how much worse our server would be without CF.
BTW, the top IPs in this burst of activity were Googlebot.
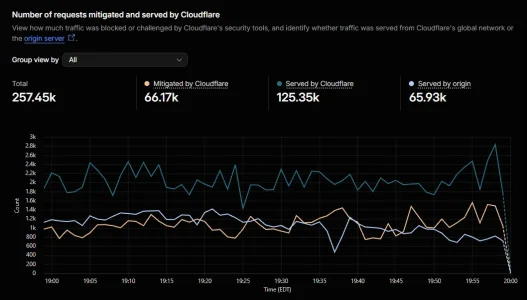
The next hour, it's back to traffic as normal, as this is pretty much where it cruises all day long.
There's no guarantee my way of doing things would help anyone else, but it's working for us, with zero complaints.
Rate limiting rule.
Does anyone use this? I don't currently, but the aforementioned spike in traffic featured Googlebot hitting us abnormally hard, apparently.
We get one free rate limiting rule in our free CF account level.
The choices in this rule are limited, and the only two that make sense are to apply it with a rule like this:
It can only rate limit based on the same IP address. (Maybe pro or business accounts have more options, but all we have is IP.
From there, we choose the number of requests per 10 seconds, and then choose a block period 10 seconds. And I have no clue what a sane value would be.
My one "nuclear option" rule I'm playing (my prior post) is likely getting rid of the residential proxies (as they won't pass the CF challenge), so this is more for the bots that I've whitelisted. I wouldn't want the search engine bots to get discouraged because they're being rate-limited.
Just thinking out loud. I've gone without using the rule, but it can't hurt to look into it.
Does anyone use this? I don't currently, but the aforementioned spike in traffic featured Googlebot hitting us abnormally hard, apparently.
We get one free rate limiting rule in our free CF account level.
The choices in this rule are limited, and the only two that make sense are to apply it with a rule like this:
(cf.bot_management.verified_bot) to apply rate limiting only to verified bots, or
(http.request.uri.path contains "") to apply rate limiting to the entire site (100% of all traffic).It can only rate limit based on the same IP address. (Maybe pro or business accounts have more options, but all we have is IP.
From there, we choose the number of requests per 10 seconds, and then choose a block period 10 seconds. And I have no clue what a sane value would be.
My one "nuclear option" rule I'm playing (my prior post) is likely getting rid of the residential proxies (as they won't pass the CF challenge), so this is more for the bots that I've whitelisted. I wouldn't want the search engine bots to get discouraged because they're being rate-limited.
Just thinking out loud. I've gone without using the rule, but it can't hurt to look into it.
I have a rate limiting rule - 10 in 10 seconds because 10 seconds is the only option on the free plan. Anything less than 10 in 10 seconds might potentially catch genuine users I thought. The problem is it does nothing much at all because my residential proxy bots only make 2 or 3 requests and then change IP so they never hit 10 in 10 seconds. They have it all worked out. However Anthropic got rate limited and had to wait 5 minutes to get going again.Rate limiting rule.
Does anyone use this? I don't currently, but the aforementioned spike in traffic featured Googlebot hitting us abnormally hard, apparently.
We get one free rate limiting rule in our free CF account level.
The choices in this rule are limited, and the only two that make sense are to apply it with a rule like this:
(cf.bot_management.verified_bot)to apply rate limiting only to verified bots, or(http.request.uri.path contains "")to apply rate limiting to the entire site (100% of all traffic).
It can only rate limit based on the same IP address. (Maybe pro or business accounts have more options, but all we have is IP.
From there, we choose the number of requests per 10 seconds, and then choose a block period 10 seconds. And I have no clue what a sane value would be.
My one "nuclear option" rule I'm playing (my prior post) is likely getting rid of the residential proxies (as they won't pass the CF challenge), so this is more for the bots that I've whitelisted. I wouldn't want the search engine bots to get discouraged because they're being rate-limited.
Just thinking out loud. I've gone without using the rule, but it can't hurt to look into it.
Cloudflare definitely saves from a disaster. Botfightmode is blocking an unbelievable amount of stuff before the high levels even got to the forum. But in terms of challenges - about 25% of my residential proxy bots get past those. I have one particular recurring one (same IP) from Myanmar who got past an ASN block and a managed challenge at site level. The only way it could get past an ASN block is if it faked being a googlebot or similar, which is what I suspect, because I whitelisted known bots. But it must also have had a fake referer to get through the managed challenge as well. Or if it was going direct to origin IP but more or less ruled that out so think it fakes being a google bot.
If it helps I found an interactive challenge on a list of countries brought the numbers down quite a bit (better than a managed challenge), but I only did that for countries I was unlikely to get members from - then a managed challenge on /whats new/ /search/ and /members/ - however I whitelisted xf_user cookie so registered members didn't get challenged, and added a referer so that genuine guests didn't get hit by a cloudflare page in the middle of browsing as didn't want to put them off staying and registering Which means a few more will get past than would do otherwise because some of them fake having a referrer. (Apparently any genuine guest will have come from another forum page first so have a "referer" - the bots go direct to whats new).
So I have the following Rules:
1) Country block - China, Mexico, Russian Federation, Hong Kong (it was the china bots that were prolific)
2) ASN block - only for countries where members unlikely to come from (I went through the guest list, once the numbers were down, looked up IP's and ASN's) whitelisting known bots (eg search engines).
3) Country challenge - Interactive challenge on about 60 countries - the worst offending ones - mostly eastern - that knocked Singapore on the head completely - some caribbean. This was the first thing that really got the numbers down.
4) URI Path Managed challenge for whats-new, members and search but mainly whats new as they all hit that straight away and scrape posts, whitelisting known bots, whitelisting xf_user cookie and referer (so registered members or genuine guests don't get challenged)
And the rate limiting rule - and bot fight mode turned on. I can't turn bot fight mode off now as it's blocking masses from huge data centres in the US - AWS, Microsoft, Alibaba and more. Those bots look like lazy or badly created ones as they have http1 and python visible so get spotted.
The residential proxy ones are the sneakiest. China ones seem to have migrated to Myanmar
I am sure there are people with better rules but that's what I have now. Numbers are right down but new ones keep appearing for eastern and caribean countries in the guest list so I go through and block a few more ASN's.
Order of rules - I think they have to fire in the right order as they work from the top down - so block rules first, then my country challenge weeds out a lot of the worst offending countries. I don't want that interactive challenge on main membership countries like Uk, US and Europe though. Any that get through the interactive challenge then get hit by the managed challenged when they hit the site whats new path challenge. Any countries not on the country challenge go straight to the whats new path for the managed challenge.
The managed challenge at the uri whats new path is weaker because I have the referer and some bots fake a referer - hence trying to knock them out with the country challenge before they get that far.
Others may have better rules/suggestions.
Last edited:
Rate limiting is excellent to deter against garbage requests. For example, this came through a little bit ago to a honeypot hostname (see attached file).
Note the rate of attack/probing speed. Rate limiting is generally good for this stuff, but not so much for AI scrapers due to the massive distribution of CIDRs in use.
Also note in the log file that it's cycling through TONS of user agents, many real-world UA's and many fake UA's. The
Note the rate of attack/probing speed. Rate limiting is generally good for this stuff, but not so much for AI scrapers due to the massive distribution of CIDRs in use.
Also note in the log file that it's cycling through TONS of user agents, many real-world UA's and many fake UA's. The
.within.website requests are the prober/exploit-check bot from 34.20.170.123 ending up deeper in the honeypot hell.Attachments
Oh this is soooooo satisfying to watch.
There's a small wave of bots trying to crawl my forum again.
They hit CloudFlare's rules.
First, they get challenged if they are not authenticated and they try some of the "expensive" or members-only URLs (search, what's new, member profiles, manage own account, private messages etc.). Only 1.01% out of a few thousand succeed.
Then they hit the blacklisted ASNs, country codes and TOR; after consuming the energy to solve the challenge, now a few hundreds are being directly blocked based on their source.
This order of the rules is intentionally picked to make it as painful/wasteful for bots as possible.
What remains is mostly residential proxies - just a few dozen at any time on the forum. Again, they hit the same URL from 2-3 different sources at the same time, and that's a clear indicator they're coordinated scrapers.
And what do they get after all that effort? A big fat nothing. Just the error page telling them that the contents they're looking for is not available unless they register an account. Guests can see only the front page with the hierarchy of categories/sections (forum nodes), but not the threads, not the authors, nothing.
If they really want to access any contents, they must have an account. And that has its own hurdles: Cloudflare Turnstile captcha, validation against StopForumSpam database, check against DNSBL and Project HoneyPot, check against some 140,000 domains for free/disposable e-mail addresses, and finally manual review and approval.
And if they pass through all of that to register, they join a "first joiners" group with very limited permissions (no URLs in profile, no signatures, all posts moderated etc.), and they have a limited time for "up or out" - they either engage meaningfully in conversations, or their registration is rejected and account disabled. We don't need lurkers and dormant bots, and we are very fine with our small community of real life friends not growing. Yeah, we have turned into cranky old men with a forum
Last edited:
And to make it all the sweeter, a honeypot that does AI text poisoning. Someone's AI scraping botnet the other day went absolutely nuts nomming all that poison per anubis logs. Looks like it was a Singapore TenCent/Aceville network once more.Oh this is soooooo satisfying to watch.
There's a small wave of bots trying to crawl my forum again.
They hit CloudFlare's rules.
First, they get challenged if they are not authenticated and they try some of the "expensive" or members-only URLs (search, what's new, member profiles, manage own account, private messages etc.). Only 1.01% out of a few thousand succeed.
Then they hit the blacklisted ASNs, country codes and TOR; after consuming the energy to solve the challenge, now a few hundreds are being directly blocked based on their source.
This order of the rules is intentionally picked to make it as painful/wasteful for bots as possible.
What remains is mostly residential proxies - just a few dozen at any time on the forum. Again, they hit the same URL from 2-3 different sources at the same time, and that's a clear indicator they're coordinated scrapers.
And what do they get after all that effort? A big fat nothing. Just the error page telling them that the contents they're looking for is not available unless they register an account. Guests can see only the front page with the hierarchy of categories/sections (forum nodes), but not the threads, not the authors, nothing.
If they really want to access any contents, they must have an account. And that has its own hurdles: Cloudflare Turnstile captcha, validation against StopForumSpam database, check against DNSBL and Project HoneyPot, check against some 140,000 domains for free/disposable e-mail addresses, and finally manual review and approval.
And if they pass through all of that to register, they join a "first joiners" group with very limited permissions (no URLs in profile, no signatures, all posts moderated etc.), and they have a limited time for "up or out" - they either engage meaningfully in conversations, or their registration is rejected and account disabled. We don't need lurkers and dormant bots, and we are very fine with our small community of real life friends not growing. Yeah, we have turned into cranky old men with a forum
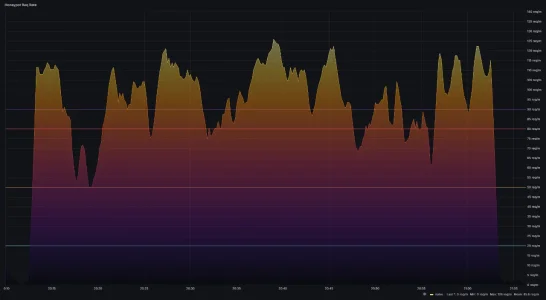
Oh, and this one just slammed into a brick wall...
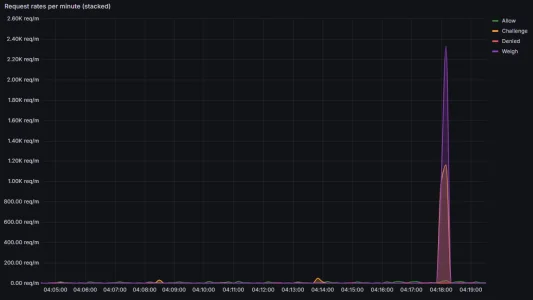
It's fairly obvious these scraper botnets at this point just don't care about where the data is hosted at, but they want it as fast as possible.
Having posted about my Cloudflare rule order earlier, I think I have 3 and 4 (after block rules 1 and 2) the wrong way round. Originally I just had the block rules at 1 and 2 and then three was the country challenge of about 60 countries - and that's when the numbers went right down - the country challenge got an awful lot of them. But it was still a bit higher than I would like so then I added the uri pathway challenge for whats-new and placed that above the country challenge.
Last night I thought - hmm that's the wrong way round. I need the country challenge first to weed out most of the culprits and then less hitting whats new, which is slightly weaker as it has a referer So I swapped them round - and numbers actually went up from average 300 to average 800 and that is still the same. So can't quite work that out - it should be better not worse. What's interesting is a lot of the countries that were being weeded out before, are now getting through again (btw these are all residential proxies). And Brazil, who I had got rid of mostly, is suddenly appearing loads of times. So could it be that it takes cloudflare longer to process rule 3 so some get through and get as far as rule 4?
This is the rule order now (previously 3 and 4 were reversed and it was working better than now)
1) Country block - China, Mexico, Russian Federation, Hong Kong (it was the china bots that were prolific)
2) ASN block - only for countries where members unlikely to come from (whitelisting known bots).
3) Interactive challenge on about 60 countries - the worst offending ones - mostly eastern and caribbean countries
4) Managed challenge for URI Path whats-new, members and search whitelisting known bots, whitelisting xf_user cookie and referer (so registered members or genuine guests don't get challenged)
Edit - I swapped 3 and 4 back round again and it works better.
Last edited:
I have most of the other stuff handled with my nuclear option and other filtering. Rate limiting is for the whitelisted bots, like Googlebot, that came in yesterday and hammered away over the course of about a half hour.Note the rate of attack/probing speed. Rate limiting is generally good for this stuff, but not so much for AI scrapers due to the massive distribution of CIDRs in use.
I just don't know a good, safe limit to try. The problem with Googlebot is that they could have, say, a dozen IPs hitting us at the same time, so it's not like a single IP is hitting us. But if I limited a single IP to 10 requests (or maybe 5 requests?) per 10 seconds, they need a slap on the wrist. Google is so fussy, they'd probably send me notices for a lot of "failures" on the site. We don't want to get delisted again since our traffic drops noticeably. (I had a rate-limiting rule in robots.txt several years ago, "crawl delay," which Googlebot doesn't even use, and yet Google still delisted us for that rule. I removed that and Googlebot's visits returned. It worked with Yahoo and others, though.)
So the rate limiter is the only remaining hole in my plan for now.
BTW, here's a little interesting tidbit from yesterday's traffic surge.
How many desktop users actually use Linux as an OS? Very small number in comparison to Windows and everything else. Yet...
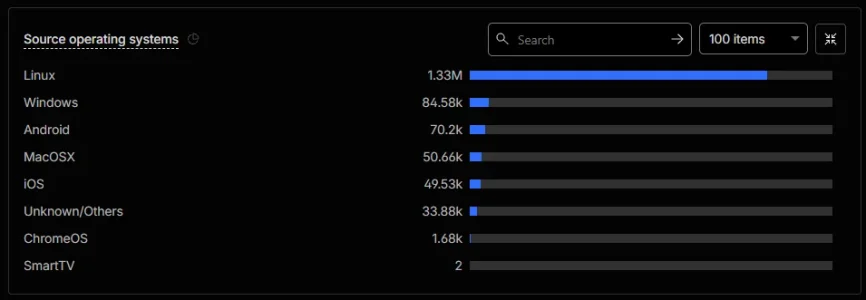
Given the demographics of the forums I admin (they tend to skew older and less technically-inclined), the number of Linux users would be far, far less than most typical forums out there. (And I don't know if the different Linux builds like Ubuntu, Mint, etc. advertise themselves as "Linux" or "Ubuntu," so...there's also that.) CF may also be lumping those into Unknown/Others also (which on CF's part, doesn't help me at all).
The SmartTV is also interesting. At first I would think it might be the compromised TVs but, since they are residential proxies that are most likely spoofing user agents, these might actually be legitimate smart TVs accessing us. (Which seems clumsy.)
Do what you will with that information. For my part, if they show Linux in http.user_agent, they get a challenge. (Don't panic--that is after my whitelisting.)
How many desktop users actually use Linux as an OS? Very small number in comparison to Windows and everything else. Yet...
Given the demographics of the forums I admin (they tend to skew older and less technically-inclined), the number of Linux users would be far, far less than most typical forums out there. (And I don't know if the different Linux builds like Ubuntu, Mint, etc. advertise themselves as "Linux" or "Ubuntu," so...there's also that.) CF may also be lumping those into Unknown/Others also (which on CF's part, doesn't help me at all).
The SmartTV is also interesting. At first I would think it might be the compromised TVs but, since they are residential proxies that are most likely spoofing user agents, these might actually be legitimate smart TVs accessing us. (Which seems clumsy.)
Do what you will with that information. For my part, if they show Linux in http.user_agent, they get a challenge. (Don't panic--that is after my whitelisting.)
Last edited:
Similar threads
- Replies
- 6
- Views
- 189


- Replies
- 8
- Views
- 222

