Crazy amount of guests

Yeah I remember there were a couple companies which tried to make this a thing - you'd get e-mail addresses with them, and for every e-mail you'd receive, their servers would send an automatic reply asking for a small payment so that the e-mail gets delivered. Ultimately it didn't catch on. Neither did the efforts of Yahoo and a few partners in their consortium to impose their own anti-spam extensions of the SMTP protocol. The SMTP protocol at large continues to work on the same decades old foundation of blind trust, with some usable enhancements like SPF and DKIM but whose adoption is still insufficient.

A complete overhaul of the e-mail protocol has been needed for at least 20 years but so far it's been cheaper (and a very lucrative business for some) to simply mitigate in various ways. Not even IPv6 didn't get massive adoption, when CGNAT with IPv4 was an easier workaround to the lack of available IPs.

So I'm a bit pessimistic about this. Unless the status quo becomes an unbearable burden for the big players who might coordinate and push for a change, the decentralized nature of the internet will be hard to shift to a completely new operating model.
 
You might be right, but they also observed issues on the official Anubis website when I asked them to check it for testing purposes. Аt that time I decided to stick with geo-blocking.
upd: in my Xenforo installation the bottleneck is redirects to posts not threads themselves. I have no idea why bots check them so agressivly.

I can't think of any good reasons why bots are doing that lately.

On my Xenforo site i'm still using fail2ban. fail2ban reads a filtered apache access log, AND the other_vhosts_access.log because there's a lot of nonsense happening there in the last 1-2 years.

Too many http requests in a day is a condition to getting banned.
No legitimate client is doing this.. but the bots are doing it a lot!
 
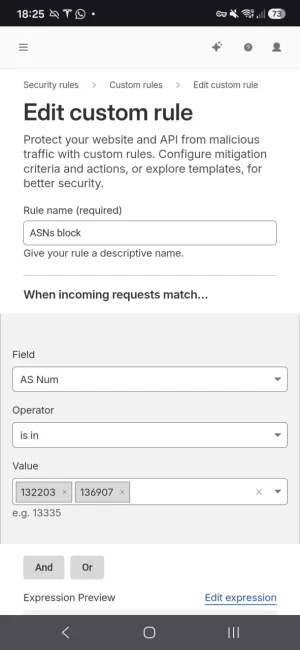
I recently discovered on cloudflare that blocking meta-externalagent wasn't working.
From what i understand, this bot is for AI training only and does not benefit the site whatsoever.

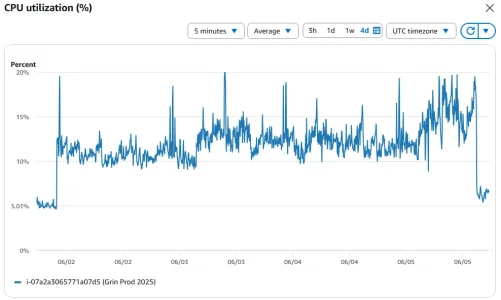
So i went back to a .htaccess ban. Pretty big impact!

1780682257194.webp
 
Honestly a good configured xenForo can easily handle even 1 million requests in a minute. We tested this on a $10 server when someone DDoS a client site. But after this when the attacks got more intensified we have up our firewalls using just CloudFlare. I think if servers and XF are configured properly these number of robots are nothing. We didn't even feel any lag in speed of website.
 
Honestly a good configured xenForo can easily handle even 1 million requests in a minute. We tested this on a $10 server when someone DDoS a client site. But after this when the attacks got more intensified we have up our firewalls using just CloudFlare. I think if servers and XF are configured properly these number of robots are nothing. We didn't even feel any lag in speed of website.

2vcpu, 2gb RAM app server. Same for the DB server within a VPC.

The DB server takes a serious hit and slows down hard when being fully scraped.

Does the configuration you mention involve static caching for guests?
 
I don't know if Cloudflare considers the residential proxies as AI-driven traffic--they may have no way of detecting it. (Or actually, if they did, we wouldn't even need this discussion.)
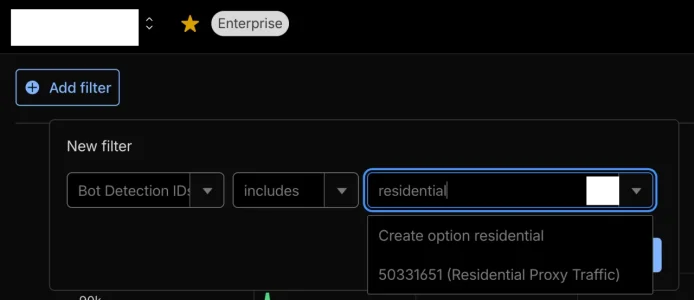
Cloudflare does detect residential proxies but you only get access to that on Cloudflare Enterprise plans via detection id WAF field https://developers.cloudflare.com/bots/additional-configurations/detection-ids/ - there's 100s (1210 ids to be exact) of detection ids available for Cloudflare Enterprise plan users :)

Detection IDs are static rules that detect predictable bot behavior with no overlap with human traffic. Each ID maps to a specific detection method such as heuristics, verified bot detections, or anomaly detections. For example, a detection ID can identify when a client sends headers in a different order than what its claimed browser would use.

If you are having an issue with one of our heuristics, detection IDs allow you to decide which heuristics to enforce on your zones using customer configurable heuristics. You can choose unique actions for different bots, detected through Cloudflare’s heuristics engine. You can block, allow, or serve alternate content to specific bots to meet the unique needs of your site’s traffic.

1780847046600.webp
 
https://ca.news.yahoo.com/ai-bots-generating-more-internet-105510959.html
I don't know if Cloudflare considers the residential proxies as AI-driven traffic--they may have no way of detecting it.
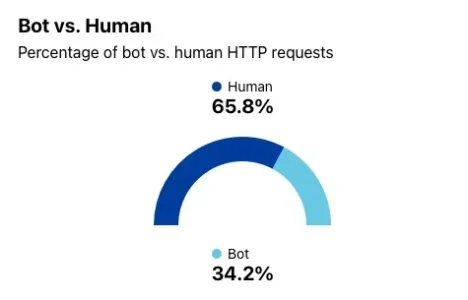
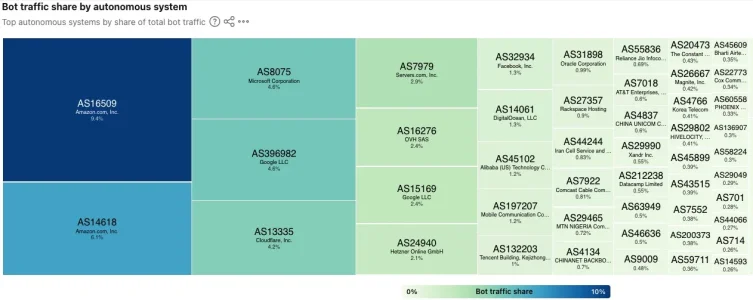
As written earlier in this thread already: Given that CF still states on their radar bots would make 34% (btw. up from the 32% they stated for ages until like last week) of traffic and humans 65%...

Bildschirm­foto 2026-06-07 um 17.44.38.webp

while on the other hand they do have some ASNs with resident proxies (like i.e. Comcast aka Spamcast, AT&T, and Iran Telecom) in their top-bot-ASN-list...Bildschirm­foto 2026-06-07 um 17.46.10.webp

... they seem to count resident proxies as bots but fail to detect them to very relevant amounts.
 
Try range blocking the ip's of all the ip's that seem to be repetitive
That is not a good solution. If a spammer uses one IP from a /24 range, then you are blocking 255 legitimate IP's for that one. Now that is different if they're using different IP's within that same block, but that is rarely the case.

Expand that - now each block is larger, then you're wiping out thousands of IP's for one bad one. That is a crazy approach if you don't want to cause legitimate users future access issues. Spammers rarely use the same IP over and over. You have to assess their behaviour before blocking, understand what they're doing and how they're doing it, otherwise you will just spend your time blocking massive amounts of good IP's.
 
The article provides no answers for server operators, only local router operators. The author reverse engineered a few things though.
https://blog.includesecurity.com/20...vingroom-is-a-node-in-the-aiscraping-economy/
F**k me! This is getting insane. Glad I don't use any of those apps on my TV's. Saying that, I have a Synology RT6600ax router and have locked our network down pretty tight, even outgoings are monitored for this type of crazy stuff. Lesson I learned... a high quality router with capabilities is essential nowadays.
 
F**k me! This is getting insane. Glad I don't use any of those apps on my TV's.
Not too new, we had this topic already a couple of months ago:

All of that. A lot has been disclosed, people just are not aware or don't care:

2024:


2025:


Bright Data was at that time already on our radar but not yet connected to fraudulent TV apps. The claim to be the "most ethical proxy provider" btw. 🤣

Another finding: At least one company that offers residential proxies:

View attachment 334929

does also offer prescraped datasets for use with AI:

View attachment 334930

So it seems they extended their business model. As usual they claim to only have "ethically sourced" residential proxies - which seems barely plausible, given the numbers of IPs they claim to have on offer:

View attachment 334931


What distinguishes this company from others is that they advertise with ISO certification and to be GDPR compliant - which by nature is barely possible in the web scraping buissiness and obviously they must be well aware that people renting residential proxies for web scraping don't give a damn about privacy protection.
View attachment 334932

They are located in Israel and seem pretty successful, given the statements on their website:

View attachment 334933View attachment 334934

In fact they seem not a shady business that is trying to hide but a "normal" company, which kind of baffled me, given the business model. They do even have a entry at wikipedia:


A pretty interesting read including some disturbing bits:

Litigation​

In July 2018, Bright Data sued another proxy service provider, Oxylabs, for patent infringement. A jury initially awarded $7.5 million in damages to Bright Data, although another judge followed that ruling by ordering the companies to undergo mediation.

In January 2023, Bright Data was sued by Meta Platforms for harvesting and selling data scraped from Facebook and Instagram. Meta previously hired Bright Data to scrape data from other websites. In January 2024, Bright Data won the dispute with Meta, where a federal judge in San Francisco declared that the company did not breach Meta's terms of use by scraping data from Facebook and Instagram, consequently denying Meta's request for summary judgment on claims of contract breach.

In July 2023, X Corp, formerly known as Twitter, sued Bright Data for scraping data from Twitter, violating its terms of service. Bright Data countersued, asserting its commitment to making public data accessible, claiming legality in its web data collection practices. In May 2024, a federal judge dismissed the suit, ruling that Bright Data did not violate X's terms of service or copyright by scraping publicly accessible data. The judge emphasized that such scraping practices are generally legal and that restricting them could lead to information monopolies, and highlighted that X's concerns were more about financial compensation than protecting user privacy.


So in two cases an US judge ruled that scraping would be legal, against big players like Meta and Twitter and despite the fact that especially on Facebook is are obviously tons of privacy related data of people and Facebook as well as Instagram and partly Twitter/X do have kind of a login wall before you can access more than just limited content. In my opinion it is simply impossible to scrape data at scale from these platforms (or from most forums) and still be in compliance with GDPR, let alone things like copyright. Either a very strange judge or a very strange legislation in the US or they do something vastly different from others. Pretty baffling.

I became curious and checked a couple of Sellers of Residential Proxies (the first hits on google) regarding where their own IP addresses belong to:

NameNo. of Proxies (claimed)No. of customers (claimed)website resolves to IP fromcompany location according to websiteDomain registered in domain created / updated
scrape.do110 Mio?cloudflareUS (but probably Turkey)? / redacted2020 / 2024
bright-data.com440 Mio+20k+cloudflareIsraelgodaddy / US privacy protection service2015 / 2026
oxylabs.io177 Mio+15k+cloudflareLT101domains / redacted2015 / 2020
webshare.io80 Mio+60k+ paid / 120k activecloudflareUS / Californianamecheap / unknown privacy protectn service2017 / 2025
proxy-seller.com20 Mio+?cloudflareCyprusnamecheap / Cyprus2015 / 2025
evomi.com30 Mio+?Framer B.V. / AS16509 (Amazon.com, Inc.)CHtucows / privacy protection service2014 / 2026
iproyal.com32 Mio+?cloudflareUAEnamers / SE privacy protection service2018 / -
dataimpulse.com90 Mio+?cloudflareUS / Floridagodaddy /US privacy protection service2008 / 2025
proxyrack.com12 Mio+?AS16509 (Amazon.com, Inc.)Fake Office in Hongkongnamecheap / IS privacy protectn service2012 / 2024

All of these services claim to only have ethically sourced proxies. 🤣 The majority hides behind Cloudflare and two are on Amazon. Which means: Cloudflare actively supports or at least tolerates scraping companies as their customers. This should in my eyes be a bit of a warning sign.
 
Back
Top Bottom